ECON 4370 / 6370 Computing for Economics

Lecture 2: R Programming (Continued)

Zhan Gao

27 August 2026

Overview

  1. Functions
  2. Packages
  3. Control Flow
  4. Iteration
  5. Statistics
  6. R Markdown and Quarto

Functions


Why write functions?

In R, we do things using functions, as soon as we use it beyond a calculator.

  • Modularity: break a complex problem into small, manageable pieces. During development you focus on one function at a time instead of the whole project.
  • Scope management: functions provide local scope. Objects created inside a function stay inside it; only inputs and outputs touch the global environment.
  • Reusability, the DRY principle: “Don’t Repeat Yourself”. When something changes, you edit one definition instead of the same code in ten places.

Calling functions

We have already seen and used a multitude of functions in R.

  • Some come pre-packaged with base R (e.g. mean())
  • Others come from external packages (e.g. mvtnorm::rmvnorm())

Regardless of where they come from, functions in R all adopt the same basic syntax:

function_name(ARGUMENTS)

Writing your own functions

Most of the time we rely on functions that other people have written for us. But you can, and should, write your own too, with the generic function() function.1

function(ARGUMENTS) {
  OPERATIONS
  return(VALUE)
}

1 Yes, it is a function that lets you write functions. Very meta.

Name your functions

Writing anonymous functions like the above is possible and reasonably common. But we typically write functions because we want to reuse code, and for that it makes sense to name them.1

my_func =
  function(ARGUMENTS) {
    OPERATIONS
    return(VALUE)
  }

Short functions need neither the curly brackets nor an explicit return object, so you can write them on a single line:

my_short_func = function(ARGUMENTS) OPERATION

1 Remember: “In R, everything is an object and everything has a name.”

Name your functions (cont.)

Tip

Try to give your functions short, pithy names that are informative to both you and anyone else reading your code. This is harder than it sounds, but will pay off down the road.

Two things we still owe you, and which the next few slides deliver:

  • when the curly brackets and the explicit return() actually matter;
  • what happens to the objects created inside the brackets.

Simple example: addition

# Built-in function
sum(c(3, 4))
## [1] 7
# User-defined function
add_func <- function(x, y) {
  total <- x + y ## Create an intermediary object (that will be returned)
  return(total) ## The value(s) or object(s) that we want returned.
}
add_func(3, 4)
## [1] 7

Return explicitly

Caution

R’s default behaviour is to automatically return the final object that you created within the function. However, this won’t always be the case. Get into the habit of assigning the return object(s) explicitly.

An explicit return() is also how we hand back more than one object:

add_func <- function(x, y) {
  total <- x + y
  return(list(sum = total, first_element = x, second_element = y))
}
add_func(3, 4)
## $sum
## [1] 7
## 
## $first_element
## [1] 3
## 
## $second_element
## [1] 4

Return explicitly (cont.)

  • Multiple return objects have to be combined in a list.
  • Naming the list elements, i.e. “sum”, “first_element” and “second_element”, is optional, but helpful for users of our function.

For this simple example we could have written everything on a single line:

my_short_add_func <- function(x, y) x + y
my_short_add_func(3, 4)
## [1] 7

Specifying default argument values

You can also assign default argument values. You have encountered examples of this already.1

add_func <- function(x = 1, y = 1) {
  total <- x + y
  return(list(total, first_element = x, second_element = y))
}

1 E.g. type ?rnorm and see that it provides a default mean and standard deviation of 0 and 1, respectively.

Specifying default argument values (cont.)

add_func()
## [[1]]
## [1] 2
## 
## $first_element
## [1] 1
## 
## $second_element
## [1] 1
add_func(3)
## [[1]]
## [1] 4
## 
## $first_element
## [1] 3
## 
## $second_element
## [1] 1
add_func(3, 4)
## [[1]]
## [1] 7
## 
## $first_element
## [1] 3
## 
## $second_element
## [1] 4

Lexical scoping

None of the intermediate objects created inside the functions above (total, etc.) made their way into our global environment. Confirm this in the “Environment” pane of RStudio.

R has a set of lexical scoping rules governing where it stores and evaluates the values of different objects.

  • Functions operate in a quasi-sandboxed environment.
  • They do not return or use objects in the global environment unless forced to, e.g. by a return() command.
  • A function only looks to outside environments, e.g. a level “up”, if it does not see the object named within itself.

Example: OLS estimation

Consider a simple linear regression model with a constant term and one regressor:

y_i = \beta_0 + \beta_1 x_i + \varepsilon_i

  • y_i: the dependent variable
  • x_i: the independent variable
  • \beta_0: the intercept, \beta_1: the slope coefficient
  • \varepsilon_i: the error term for observation i

Example: OLS estimation (cont.)

In matrix notation:

\mathbf{y} = \mathbf{X}\boldsymbol{\beta} + \boldsymbol{\varepsilon}

  • \mathbf{y} is an n \times 1 vector of dependent variable observations
  • \mathbf{X} is an n \times 2 matrix: the first column all ones (for the intercept), the second the x_i values
  • \boldsymbol{\beta} = \begin{bmatrix} \beta_0 \\ \beta_1 \end{bmatrix} is a 2 \times 1 vector of parameters
  • \boldsymbol{\varepsilon} is an n \times 1 vector of error terms

The OLS estimator is given by

\hat{\boldsymbol{\beta}} = (\mathbf{X}' \mathbf{X})^{-1} \mathbf{X}'\mathbf{y}

To conduct OLS estimation in R, we literally translate this mathematical expression into code.

Step 1: simulate the data

We need data Y and X to run OLS, so we simulate an artificial dataset.

# simulate data
set.seed(111) # can be removed to allow the result to change

# set the parameters
n <- 100
b0 <- matrix(1, nrow = 2)

# generate the data
e <- rnorm(n)
X <- cbind(1, rnorm(n))
Y <- X %*% b0 + e

Step 1: simulate the data (cont.)

# Snapshot of X (first 10 rows):
print(head(X, 10))
##       [,1]       [,2]
##  [1,]    1  0.5996197
##  [2,]    1 -1.1603295
##  [3,]    1  0.4390934
##  [4,]    1  0.2048537
##  [5,]    1 -0.6991813
##  [6,]    1 -0.9266257
##  [7,]    1 -1.0134824
##  [8,]    1  0.6049871
##  [9,]    1  1.7344001
## [10,]    1 -0.3498505
# Snapshot of Y (first 10 elements):
print(head(Y, 10))
##             [,1]
##  [1,]  1.8348405
##  [2,] -0.4910654
##  [3,]  1.1274696
##  [4,] -1.0974919
##  [5,]  0.1299426
##  [6,]  0.2136525
##  [7,] -1.5109090
##  [8,]  0.5947986
##  [9,]  1.7859245
## [10,]  0.1561873

Step 2: translate the formula to code

\hat{\boldsymbol{\beta}} = (\mathbf{X}' \mathbf{X})^{-1} \mathbf{X}'\mathbf{y} becomes one line of R.

# OLS estimation
bhat <- solve(t(X) %*% X, t(X) %*% Y)
print(bhat)
##           [,1]
## [1,] 0.9861773
## [2,] 0.9404956
class(bhat)
## [1] "matrix" "array"

solve(A, b) solves Ax = b, which is numerically better behaved than forming the inverse with solve(A) %*% b.

Step 2: wrap it in a function

# User-defined function
ols_est <- function(X, Y) {
  bhat <- solve(t(X) %*% X, t(X) %*% Y)
  return(bhat)
}
bhat_2 <- ols_est(X, Y)
print(bhat_2)
##           [,1]
## [1,] 0.9861773
## [2,] 0.9404956
class(bhat_2)
## [1] "matrix" "array"

Step 2: or use a built-in function

# Use built-in functions
bhat_3 <- lsfit(X, Y, intercept = FALSE)$coefficients
print(bhat_3)
##        X1        X2 
## 0.9861773 0.9404956
class(bhat_3)
## [1] "numeric"

Same numbers, three routes. Note that the returned class differs.

Step 3: plot the regression

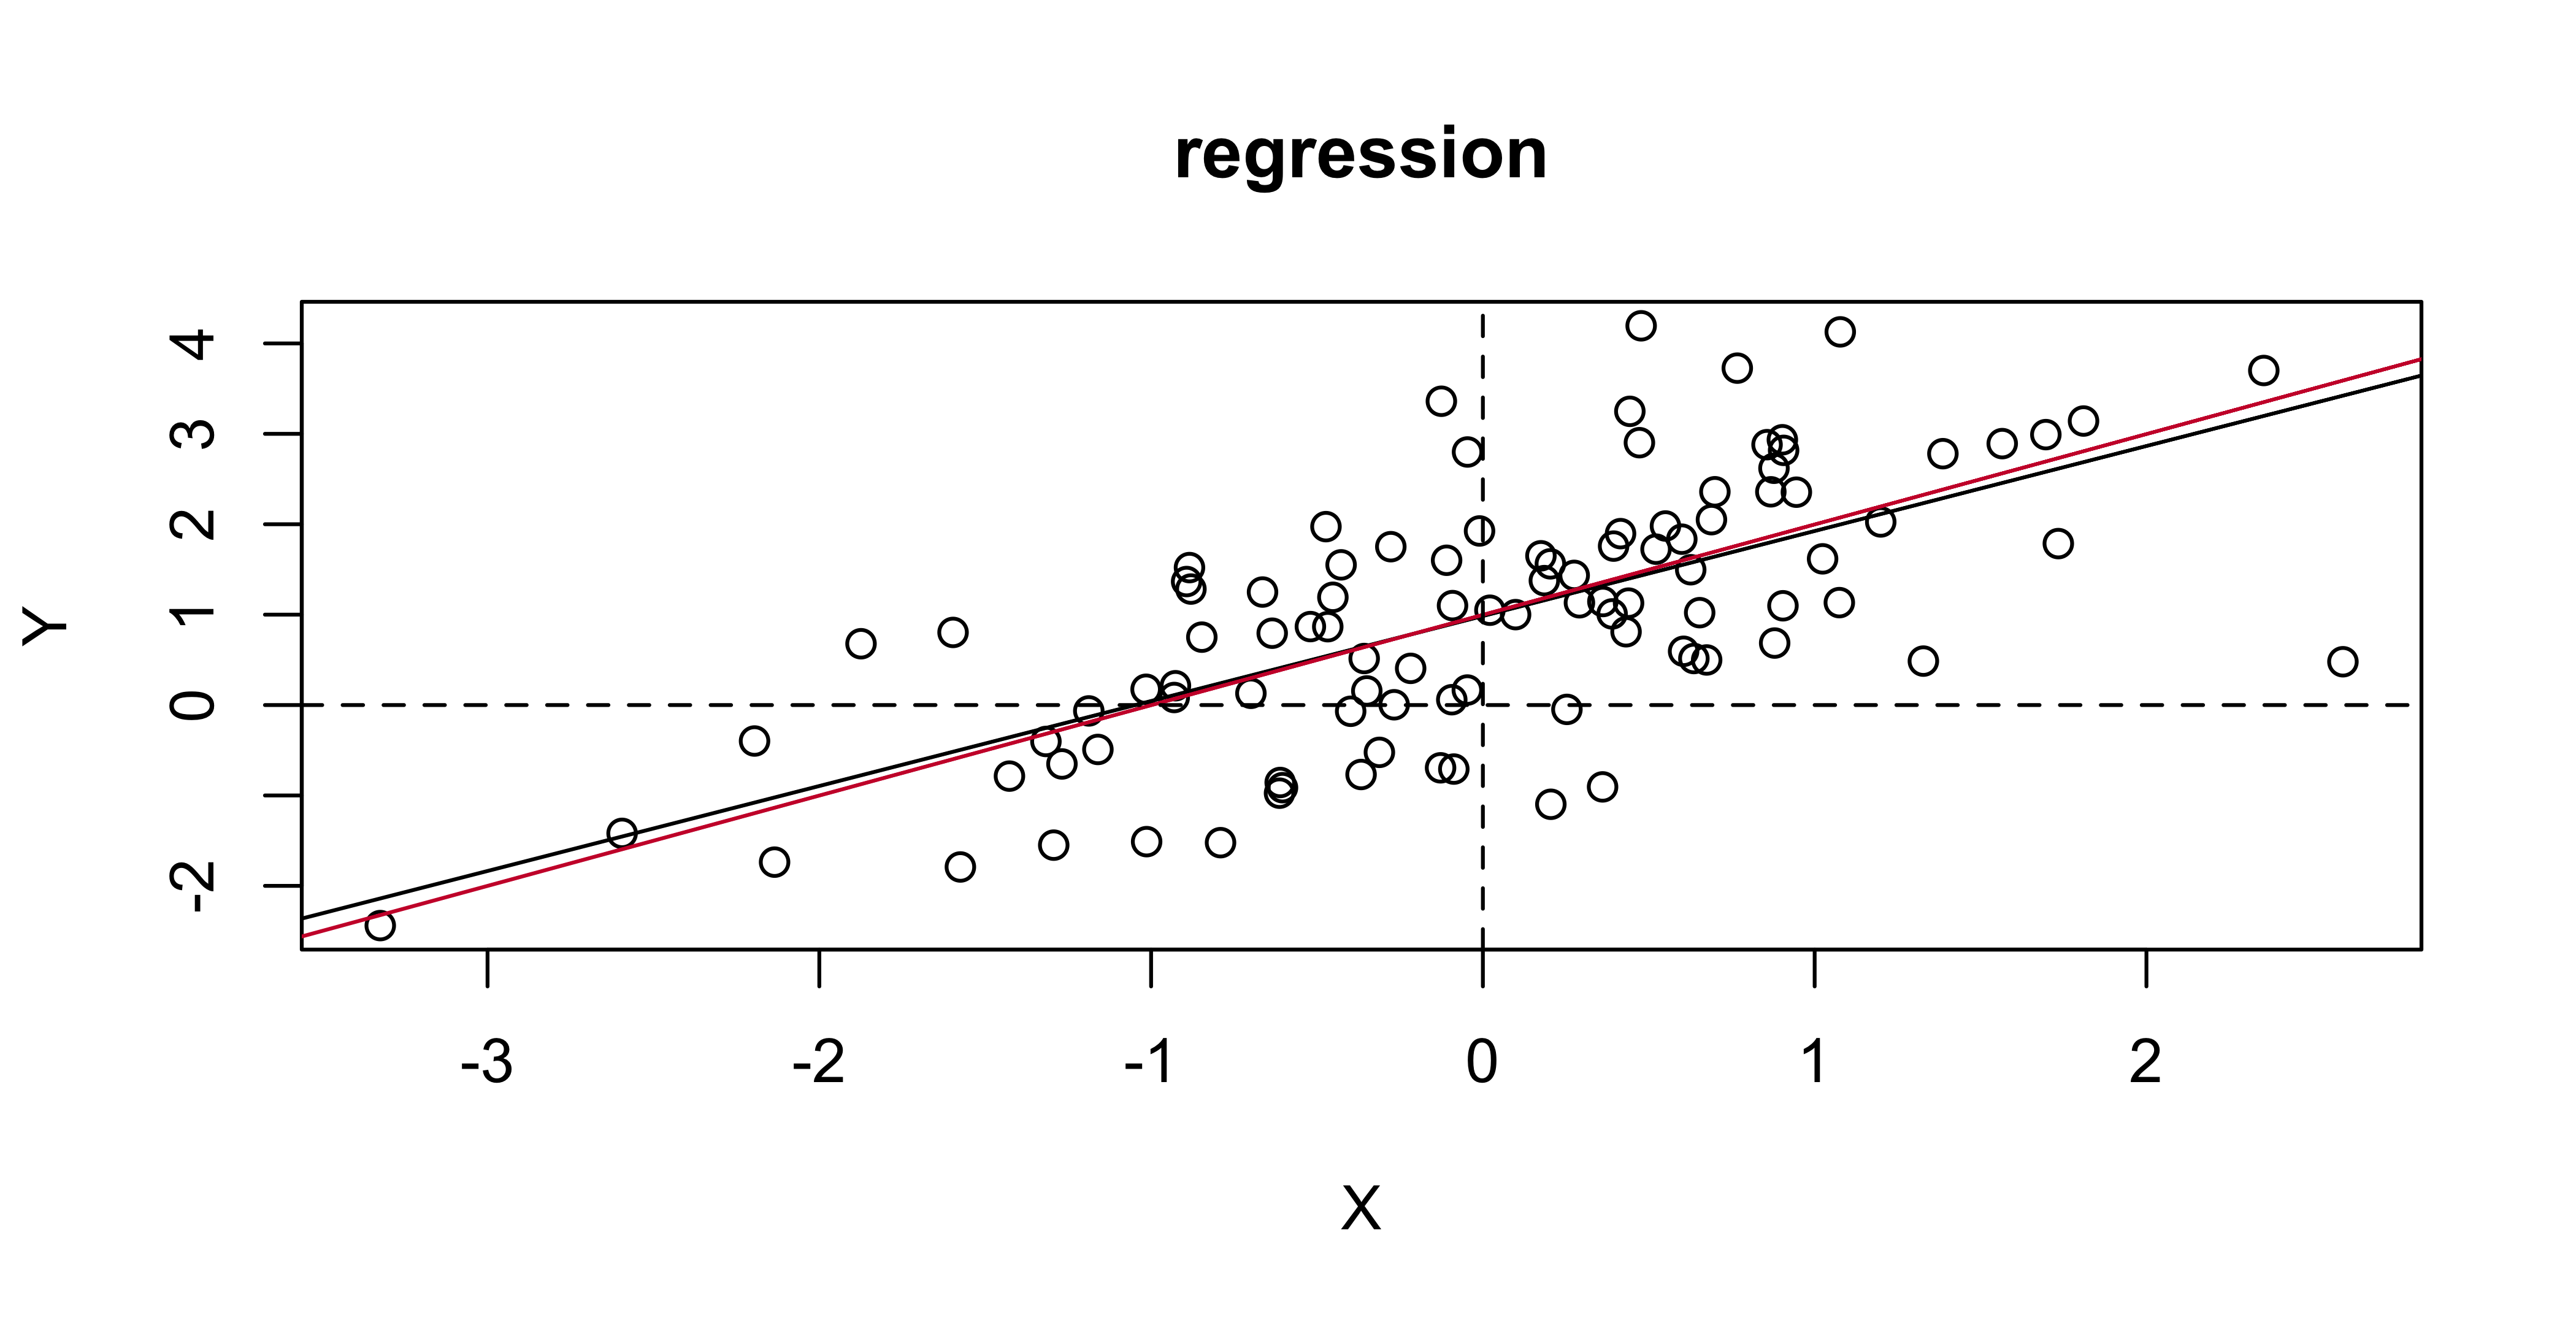
Scatter points, the fitted regression line (black) and the true coefficient line (red).

plot(y = Y, x = X[, 2], xlab = "X", ylab = "Y", main = "regression")
abline(a = bhat[1], b = bhat[2])
abline(a = b0[1], b = b0[2], col = "#CC0035")
abline(h = 0, lty = 2)
abline(v = 0, lty = 2)

Step 4: hypothesis testing

In econometrics we are often interested in hypothesis testing, and the t-statistic is widely used. To test H_0: \beta_1 = 1, again a translation:

t = \frac{\hat{\beta}_1 - \beta_{01}}{ \hat{\sigma}_{\hat{\beta}_1} } = \frac{\hat{\beta}_1 - \beta_{01}}{ \sqrt{ \left[ (X'X)^{-1} \hat{\sigma}^2 \right]_{22} } },

where [\cdot]_{22} is the (2,2)-element of a matrix.

Step 4: hypothesis testing (cont.)

# calculate the t-value
bhat2 <- bhat[2] # the parameter we want to test
e_hat <- Y - X %*% bhat
sigma_hat_square <- sum(e_hat^2) / (n - 2)
Sigma_B <- solve(t(X) %*% X) * sigma_hat_square
t_value_2 <- (bhat2 - b0[2]) / sqrt(Sigma_B[2, 2])
print(t_value_2)
## [1] -0.5615293

Exercise (in Homework 1): can you write a function with both \hat{\beta} and the t-value as outputs?

Accessing function source code

Looking inside a function is not only important for debugging, it is also a great way to pick up programming tips and tricks.

  • For simple functions: type the function name into the console without parentheses and let R print the object, e.g. dplyr::bind_rows.
  • This breaks down for functions with dispatch methods (S3/S4 classes) or compiled code underneath (C, Fortran).

You can still view the source, it just takes more legwork:

Packages


R’s package ecosystem

A base R installation is relatively compact. R’s true power lies in its extensive ecosystem of add-on packages, most of them hosted on CRAN, the Comprehensive R Archive Network.

A common practice in the statistical community: researchers publish an R package alongside the academic paper.

  • New statistical methods become immediately accessible to practitioners.
  • A virtuous cycle: researchers gain visibility, users get cutting-edge tools within months, sometimes weeks, of publication.

Install and load packages

A package is installed by install.packages("package_name") and invoked by library(package_name).

To install ggplot2, either:

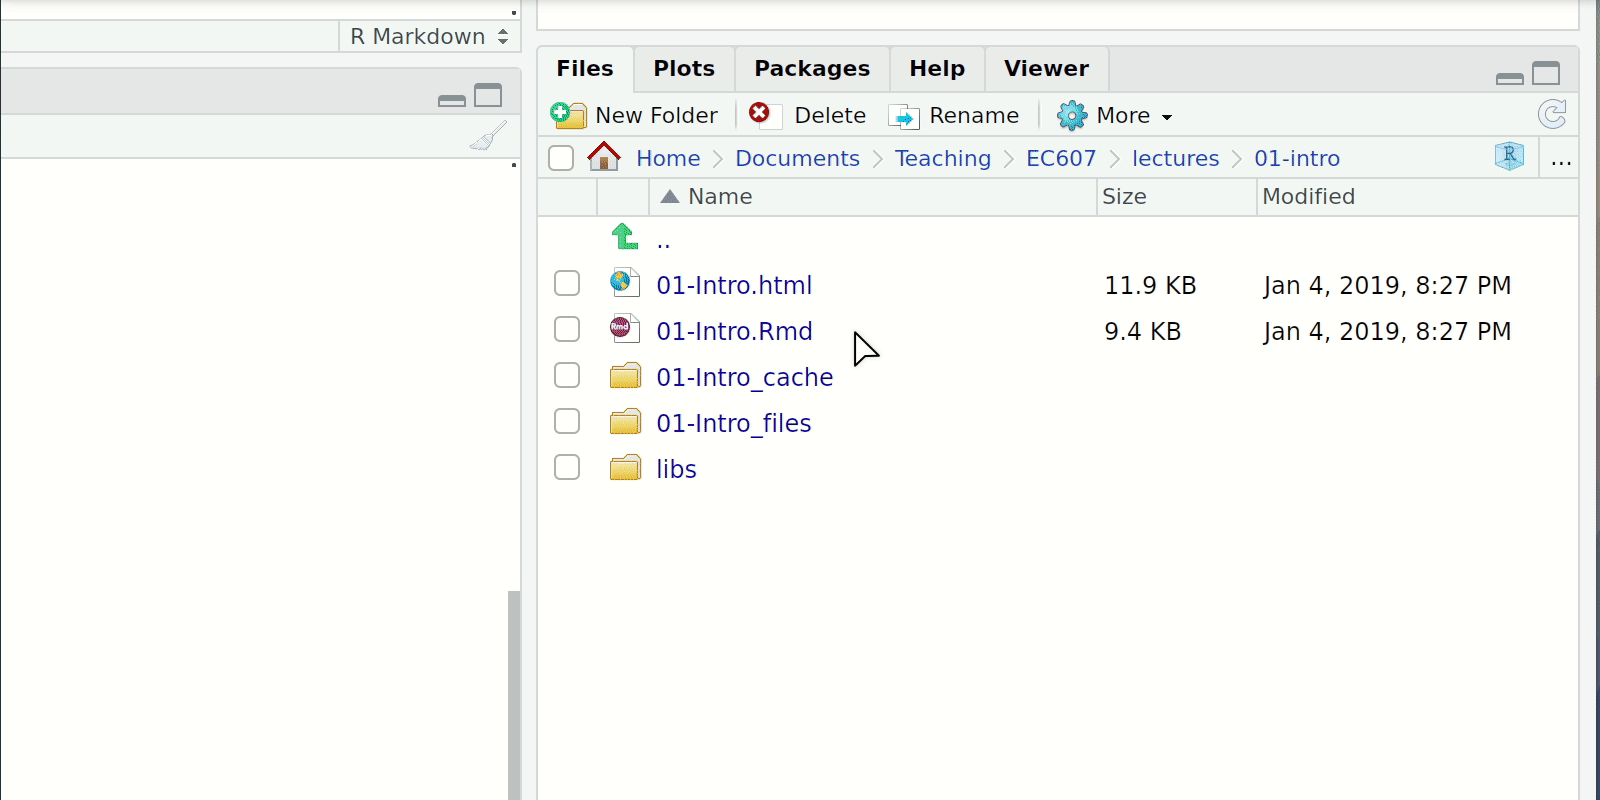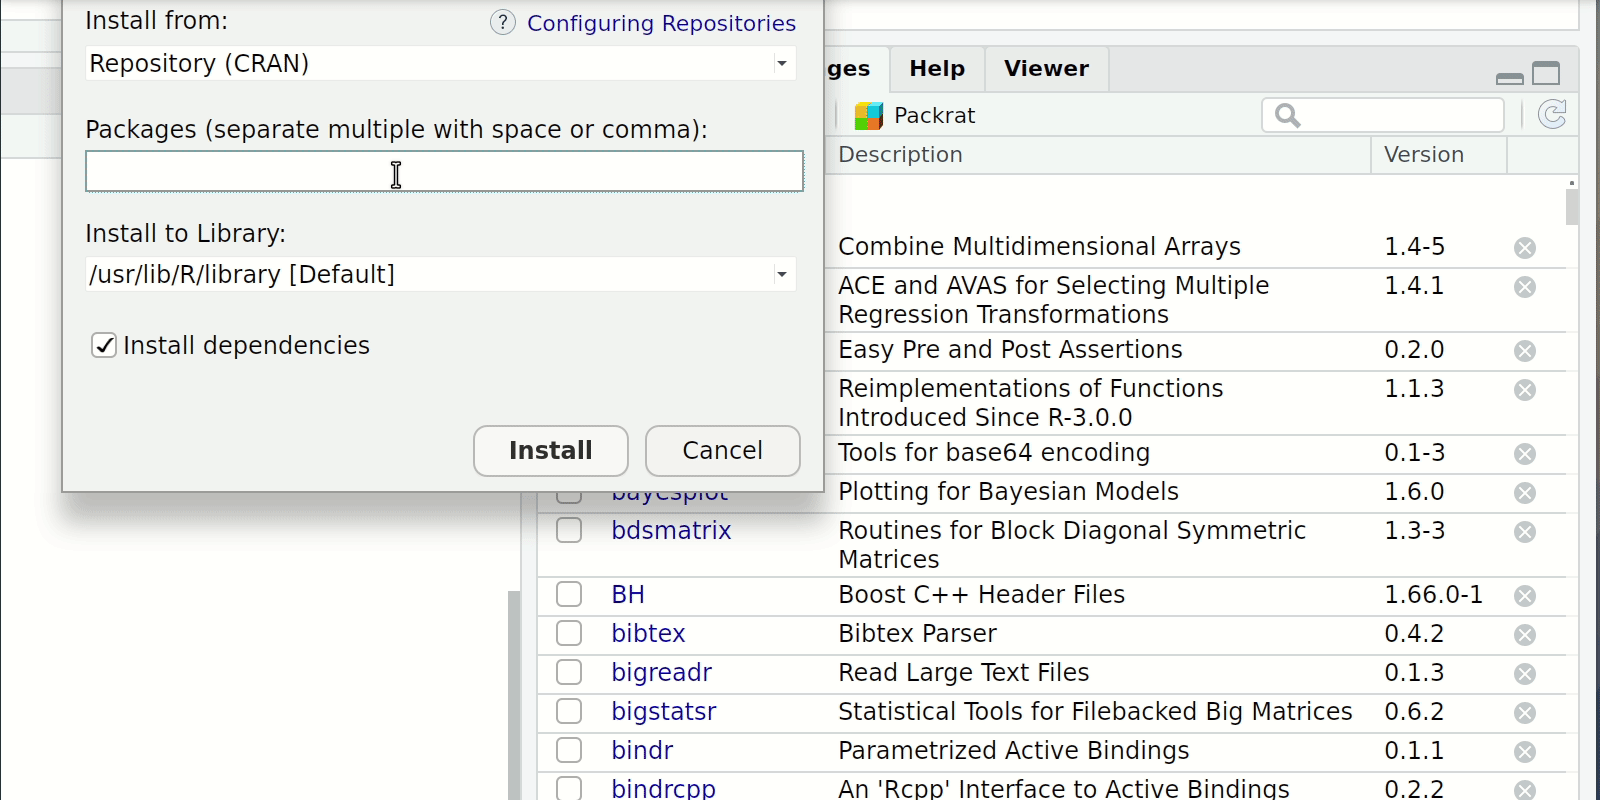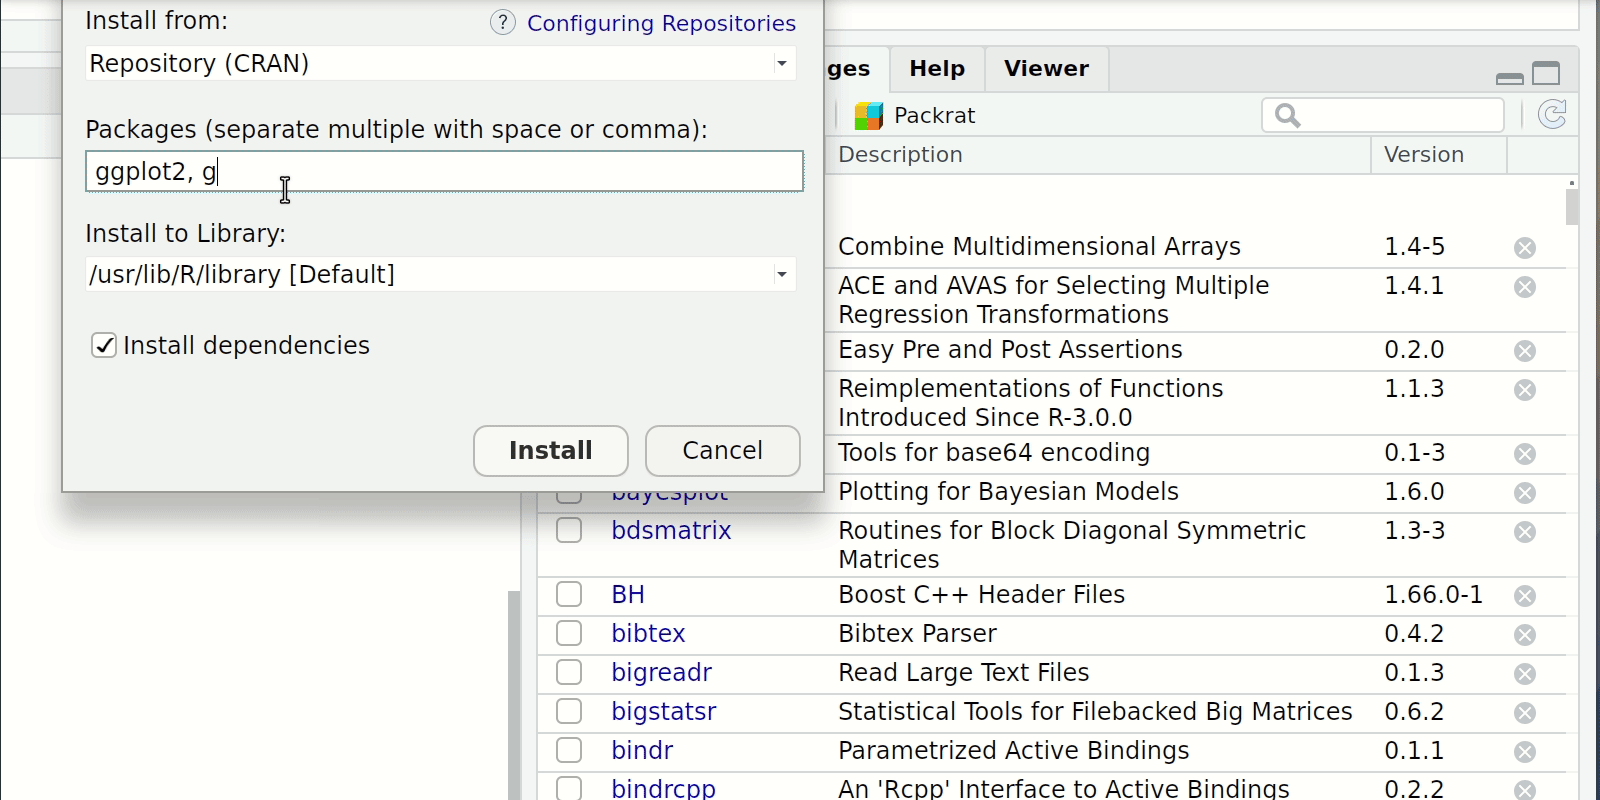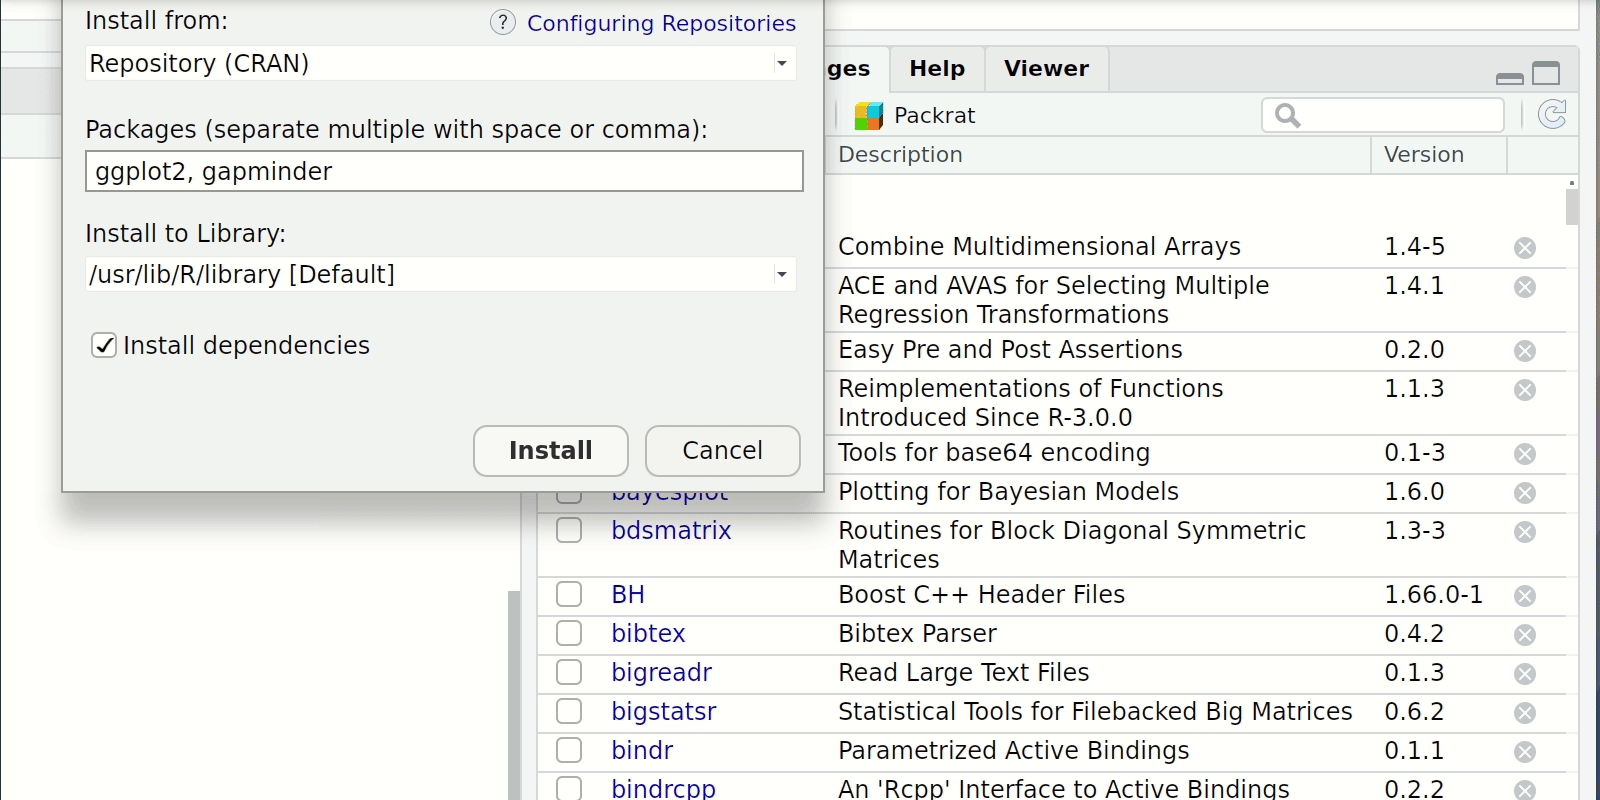
  • Console: enter install.packages("ggplot2").
  • RStudio: click the “Packages” tab in the bottom-right pane, then “Install”, and search for the package.

Install and load packages (cont.)

Loading packages

Once installed, load a package into your R session with library().

library(ggplot2)

Note

Notice that you do not need quotes around the package name any more.

Reason: R now recognizes the package as a defined object with a given name. (“Everything in R is an object and everything has a name.”)

Shortcuts and namespaces

Tip

A convenient way to combine installation and loading is the pacman package’s p_load() function. pacman::p_load(ggplot2) first checks whether it needs to install the package, then loads it. Clever.

We can also run a function from an installed package without loading it, using PACKAGE::package_function():

stats::sd(1:10)
## [1] 3.02765

Packages beyond CRAN

Many authors distribute packages through GitHub or their personal websites, especially for cutting-edge research or development versions.

  • Install them with devtools or remotes.
  • Follow the instructions on the project’s repository, e.g. RDHonest.
if (!requireNamespace("remotes")) {
  install.packages("remotes")
}
remotes::install_github("kolesarm/RDHonest")

Build your own packages

Why build a package?

  • Share and reuse code across projects
  • Enforce conventions and structure
  • Improve reproducibility and collaboration

Core tools: RStudio Projects, usethis, devtools, roxygen2, testthat, knitr, styler.

The standard reference is Wickham and Bryan’s R Packages.

Step 0: system setup

install.packages(c("usethis", "devtools", "roxygen2", "testthat", "knitr", "styler"))
devtools::has_devel() # Check build toolchain (compilers, etc.)

Working practice

  • Keep your R session’s working directory at the package root.
  • Iterate with devtools::load_all() for fast feedback.
  • Run devtools::check() often to catch issues early.

Step 1: create a package skeleton

usethis::create_package("~/dev/eco4370") # choose your path
# RStudio will open the new project; from there:
usethis::use_git() # initialize Git repo
usethis::use_mit_license("Your Name") # add a license

Edit DESCRIPTION early: Title, Description, Authors, Imports.

  • Prefer Imports: over Depends:.
  • Pin versions only when you really need to.

Step 2: add functions (with roxygen docs)

Create an R script and a function:

usethis::use_r("math") # creates R/math.R
# file: R/math.R
#' Add two numbers
#'
#' @param x numeric
#' @param y numeric
#' @return numeric
#' @export
#' @examples
#' add(1, 2)
add <- function(x, y) {
  x + y
}

Step 2: the development loop

Generate docs and namespace, then try it out without installing:

devtools::document() # creates man/*.Rd and updates NAMESPACE
devtools::load_all() # simulate attach for development
add(1, 2)

Edit → document → load_all → test → check is the core loop for fast feedback.

Step 3: testing

usethis::use_testthat()
usethis::use_test("add") # creates tests/testthat/test-add.R
# file: tests/testthat/test-add.R
test_that("add works", {
  expect_equal(add(1, 1), 2)
  expect_error(add("a", 1))
})

Run tests with devtools::test().

Step 4: manage dependencies

If your functions use other packages:

usethis::use_package("forcats") # adds to Imports
# call explicitly as forcats::fct_unify(...),
# unless you import specific functions with @importFrom in roxygen

Best practices

  • Prefer pkg::fun() in code.
  • Avoid library() inside package code.
  • Keep Imports: tidy and alphabetical in DESCRIPTION.

Step 5: project hygiene and style

  • Group related functions together. Avoid one giant file, and avoid one file per tiny function.
  • Avoid global side-effects: no setwd(), options(), par(), Sys.setenv(), set.seed() in package code.
  • Never use source() or library() inside R/ package code.
  • Style regularly:
styler::style_pkg()

Step 6: README, GitHub, and visibility

usethis::use_readme_rmd()
devtools::build_readme()

usethis::use_github() # creates remote, sets origin, and optionally pushes

This makes your package discoverable and easier to collaborate on.

Step 7: vignettes

Vignette = long-form documentation.

usethis::use_vignette("eco4370-intro")
# Knit within the vignette to preview; pkg build will render it

Step 7: data

  • User-facing datasets go in data/ via use_data(), documented in R/data.R. Never @export datasets.
  • Internal data for functions: use_data(..., internal = TRUE) writes R/sysdata.rda, no help file needed.
  • Raw sources and the scripts that create data: data-raw/, added to .Rbuildignore.
# Example: create an excerpted dataset
dir.create("data-raw", showWarnings = FALSE)
write.csv(mtcars, "data-raw/mtcars.csv", row.names = FALSE)

cars_small <- mtcars[1:8, 1:4]
usethis::use_data(cars_small, overwrite = TRUE) # creates data/cars_small.rda

Step 7: documenting a dataset

Document the dataset in R/data.R:

#' Small Car Dataset
#'
#' A tiny excerpt of mtcars for examples.
#'
#' @format A data frame with 8 rows and 4 variables.
#' @source Base R `mtcars`
"cars_small"

Step 8: check, install, build

devtools::check() # CRAN-style QA
devtools::install() # local install
devtools::build() # source tarball; build(binary = TRUE) for binary on your OS

Know the package states:

source → bundled → binary → installed → in-memory

Worked mini-example: eco4370


A compact, end-to-end demo that you can reproduce.

1) Create and initialize

usethis::create_package("~/dev/eco4370")
usethis::use_git()
usethis::use_mit_license("Your Name")

1) Update DESCRIPTION

# text
Package: eco4370
Title: Simple Utilities for Teaching Package Development
Version: 0.0.0.9000
Authors@R: person("Your", "Name", email = "you@smu.edu", role = c("aut","cre"))
Description: Minimal examples (functions, tests, vignette, and data) for ECO 4370/6370.
License: MIT + file LICENSE
Encoding: UTF-8
Roxygen: list(markdown = TRUE)
Depends: R (>= 4.2)
Imports:
    stats
Suggests:
    testthat (>= 3.0.0),
    knitr,
    rmarkdown
VignetteBuilder: knitr
URL: https://github.com/yourname/eco4370
BugReports: https://github.com/yourname/eco4370/issues

2) Add two small functions

usethis::use_r("math")
# file: R/math.R
#' Add two numbers
#' @param x,y numeric
#' @return numeric
#' @export
#' @examples
#' add(2, 3)
add <- function(x, y) x + y

#' Moving average (center = FALSE by default)
#' @param x numeric vector
#' @param k window size (integer >= 1)
#' @param center logical; if TRUE, centered window
#' @return numeric vector of smoothed values
#' @export
#' @examples
#' movavg(1:5, k = 3)
movavg <- function(x, k = 3, center = FALSE) {
  stopifnot(is.numeric(x), k >= 1, k == as.integer(k))
  if (!center) {
    stats::filter(x, rep(1 / k, k), sides = 1)
  } else {
    stats::filter(x, rep(1 / k, k), sides = 2)
  }
}

2) Document and try

devtools::document()
devtools::load_all()
add(2, 3)
movavg(1:6, 3)

3) Tests

usethis::use_testthat()
usethis::use_test("math")
# file: tests/testthat/test-math.R
test_that("add works", {
  expect_equal(add(2, 3), 5)
  expect_error(add("a", 1))
})

test_that("movavg works", {
  x <- 1:6
  out <- movavg(x, k = 3)
  expect_equal(length(out), length(x))
  expect_true(is.numeric(out))
})

Run with devtools::test().

4) Data, user-facing and internal

dir.create("data-raw", showWarnings = FALSE)
write.csv(mtcars, "data-raw/mtcars.csv", row.names = FALSE)

cars_small <- mtcars[1:8, 1:4]
usethis::use_data(cars_small, overwrite = TRUE) # creates data/cars_small.rda
# file: R/data.R
#' Small Car Dataset
#'
#' A tiny excerpt of mtcars for examples.
#'
#' @format A data frame with 8 rows and 4 variables.
#' @source Base R `mtcars`
"cars_small"

For internal helper data: usethis::use_data(obj, internal = TRUE) writes R/sysdata.rda, no help file.

5) Vignette

usethis::use_vignette("getting-started")

Edit vignettes/getting-started.Rmd:

# markdown
---
title: "Getting Started with eco4370"
output: rmarkdown::html_vignette
vignette: >
  %\VignetteIndexEntry{Getting Started}
  %\VignetteEngine{knitr::rmarkdown}
  %\VignetteEncoding{UTF-8}
---

5) Vignette: basic usage

add(10, 5)
movavg(1:10, k = 3)
cars_small

Preview by knitting. When building the package, vignettes are rendered automatically.

6) README and GitHub, 7) final checks

usethis::use_readme_rmd()
devtools::build_readme()

usethis::use_github() # requires a GitHub account + token set up
devtools::check() # fix NOTES/WARNINGS/ERRORS
devtools::install() # local install
devtools::build() # source tar.gz
# devtools::build(binary = TRUE)  # platform-specific binary (optional)

Common gotchas

  • Don’t call library() or source() inside package code.
  • Keep non-function top-level code out of R/. Code in R/ runs at build time.
  • Prefer pkg::fun() unless you explicitly import with @importFrom.
  • Keep .Rbuildignore tidy:
# text
^.*\.Rproj$
^\.Rproj\.user$
^README\.Rmd$
^data-raw$
^\.github$
^_pkgdown\.yml$

One-page workflow

  1. create_package() → open project
  2. use_git() → commit
  3. use_r() → write function(s) in R/
  4. roxygen comments → document()
  5. load_all() to try code
  1. use_testthat() → write tests → test()
  2. use_package() for deps (avoid library() in code)
  3. (Optional) use_vignette(), use_data()
  4. use_readme_rmd() → build_readme()
  5. check() → install() → build() → (optional) use_github()

Literate programming

A modern approach to developing R packages is through literate programming.

  • The litr package, by Jacob Bien, lets you write a complete R package inside a single R Markdown document.
  • The package is created when you knit the Rmd file.
  • For larger packages, you can write a bookdown that defines the package.

Interested? The videos show how it works in a few minutes.

Control Flow


Controlling the flow

Now that we have a good sense of the basic function syntax, it is time to learn control flow: controlling the order, or “flow”, of the statements and operations that our functions evaluate.

This is common to all programming languages.

  • if is used for choice.
  • for and while are used for loops.

if

The basic syntax for an if statement:

if (CONDITION) {
  OPERATION
}
square_root <- function(x) {
  if (x < 0) {
    message("x is negative")
    return(NA)
  }
  return(sqrt(x))
}
square_root(9)
## [1] 3
square_root(-9)
## x is negative
## [1] NA

if ... else

We can extend this with an else statement to handle alternative conditions:

square_root <- function(x) {
  if (x < 0) {
    message("x is negative")
    return(NA)
  } else {
    return(sqrt(x))
  }
}

ifelse()

For simple conditional operations, ifelse() provides a more concise syntax:

ifelse(CONDITION, DO IF TRUE, DO IF FALSE)

In our example, ifelse() gives a simpler version of square_root():

square_root <- function(x) {
  ifelse(x < 0, NA, sqrt(x))
}

A “gotcha” with ifelse()

Warning

The base R ifelse() function normally works great, and I use it all the time. But there are a couple of “gotcha” cases you should be aware of.

Consider this silly function, designed to return either today’s date or the day before:

print(Sys.Date())
## [1] "2026-08-27"
print(Sys.Date() - 1)
## [1] "2026-08-26"
today <- function(...) ifelse(..., Sys.Date(), Sys.Date() - 1)
today(TRUE)
## [1] 20692

A number, not a date!

A “gotcha” with ifelse() (cont.)

Why: ifelse() automatically converts date objects to numeric, as a way to get around some other type conversion strictures.

  • Confirm it for yourself by converting back the other way: as.Date(today(TRUE), origin = "1970-01-01").

Aside: the “dot-dot-dot” argument (...) used above is a convenient shortcut that allows users to enter unspecified arguments into a function.

  • Beyond the scope of this lecture, but an incredibly useful and flexible programming strategy.
  • See the relevant section of Advanced R.

Safer alternatives

To guard against this behaviour, and to add some other optimisations, both the tidyverse (through dplyr) and data.table offer their own versions of ifelse.

First, dplyr::if_else():

today2 <- function(...) {
  dplyr::if_else(..., Sys.Date(), Sys.Date() - 1)
}
today2(TRUE)
## [1] "2026-08-27"

Second, data.table::fifelse():

today3 <- function(...) {
  data.table::fifelse(..., Sys.Date(), Sys.Date() - 1)
}
today3(TRUE)
## [1] "2026-08-27"

Nested ifelse()

As you may have guessed, it is certainly possible to write nested ifelse() statements:

ifelse(CONDITION1, DO IF TRUE, ifelse(CONDITION2, DO IF TRUE, ifelse(...)))

or

if (CONDITION1) {
  DO IF TRUE
} else if (CONDITION2) {
  DO IF TRUE
} else {
  DO IF FALSE
}

However, these nested statements quickly become difficult to read and troubleshoot.

case when

A better solution was originally developed in SQL with the CASE WHEN statement. Both dplyr (case_when()) and data.table (fcase()) provide implementations in R.

x <- 1:10
## dplyr::case_when()
case_when(
  x <= 3 ~ "small",
  x <= 7 ~ "medium",
  TRUE ~ "big" ## Default value. Could also write `x > 7 ~ "big"` here.
)
##  [1] "small"  "small"  "small"  "medium" "medium" "medium" "medium" "big"   
##  [9] "big"    "big"
## data.table::fcase()
fcase(
  x <= 3, "small",
  x <= 7, "medium",
  default = "big" ## Default value. Could also write `x > 7, "big"` here.
)
##  [1] "small"  "small"  "small"  "medium" "medium" "medium" "medium" "big"   
##  [9] "big"    "big"

Iteration


Iteration

Alongside control flow, the most important early programming skill to master is iteration.

In particular, we want to write functions that can iterate, or map, over a set of inputs.

for loops

By far the most common way to iterate, across programming languages, is the for loop.

for (i in 1:3) {
  x <- rnorm(i)
  print(x)
}
## [1] -0.2986997
## [1] -0.5935356  0.8267038
## [1] -2.1614064 -0.9210425  0.5171631

Minimize the work inside a loop

When we use loops, we should minimize the tasks within the loop.

  • Pre-specify the dimension and allocate memory for variables outside the loop.
  • In cases where we want to “grow” an object via a for loop, we first have to create an empty (or NULL) object, and R re-allocates memory at every iteration.

Let us measure how much this actually costs.

Example: empirical coverage of a confidence interval

CI <- function(x) {
  # construct confidence interval
  # x is a vector of random variables
  n <- length(x)
  mu <- mean(x)
  sig <- sd(x)
  upper <- mu + 1.96 / sqrt(n) * sig
  lower <- mu - 1.96 / sqrt(n) * sig
  return(list(lower = lower, upper = upper))
}

Rep <- 100000
sample_size <- 1000
mu <- 2

Option 1: append a new outcome after each loop

pts0 <- Sys.time() # check time
for (i in 1:Rep) {
  x <- rpois(sample_size, mu)
  bounds <- CI(x)
  out_i <- ((bounds$lower <= mu) & (mu <= bounds$upper))
  if (i == 1) {
    out <- out_i
  } else {
    out <- c(out, out_i)
  }
}
mean(out)
## [1] 0.95023
cat("Takes", Sys.time() - pts0, "seconds\n")
## Takes 7.476734 seconds

Option 2: initialize the result vector

# Initialize the result vector
out <- rep(0, Rep)
pts0 <- Sys.time() # check time
for (i in 1:Rep) {
  x <- rpois(sample_size, mu)
  bounds <- CI(x)
  out[i] <- ((bounds$lower <= mu) & (mu <= bounds$upper))
}
mean(out)
## [1] 0.94893
cat("Takes", Sys.time() - pts0, "seconds\n")
## Takes 2.480385 seconds

Identical answer, and the empirical coverage sits close to the nominal 95%. Pre-allocating is the cheaper route.

Vectorization

Before we write any loops, we should ask ourselves: “Do I need to iterate at all?”

R is vectorized. Often you can apply a function to every element of a vector at once, rather than one at a time.

a_vec <- c(1, 2, 3)
b_vec <- c(4, 5, 6)

c_vec <- rep(NA, length(a_vec))
for (i in 1:length(a_vec)) {
  c_vec[i] <- a_vec[i] * b_vec[i]
}
c_vec

… or just a_vec * b_vec.

Why vectorize?

  • In R and other high-level languages, for loops can be slow. When you loop through many elements and perform an expensive operation on each one, your code may take a long time to execute.
  • Many operations typically implemented with for-loops can be rewritten using vectorized operations or matrix computations.
  • Whenever possible, leverage R’s built-in vectorization capabilities for better performance.

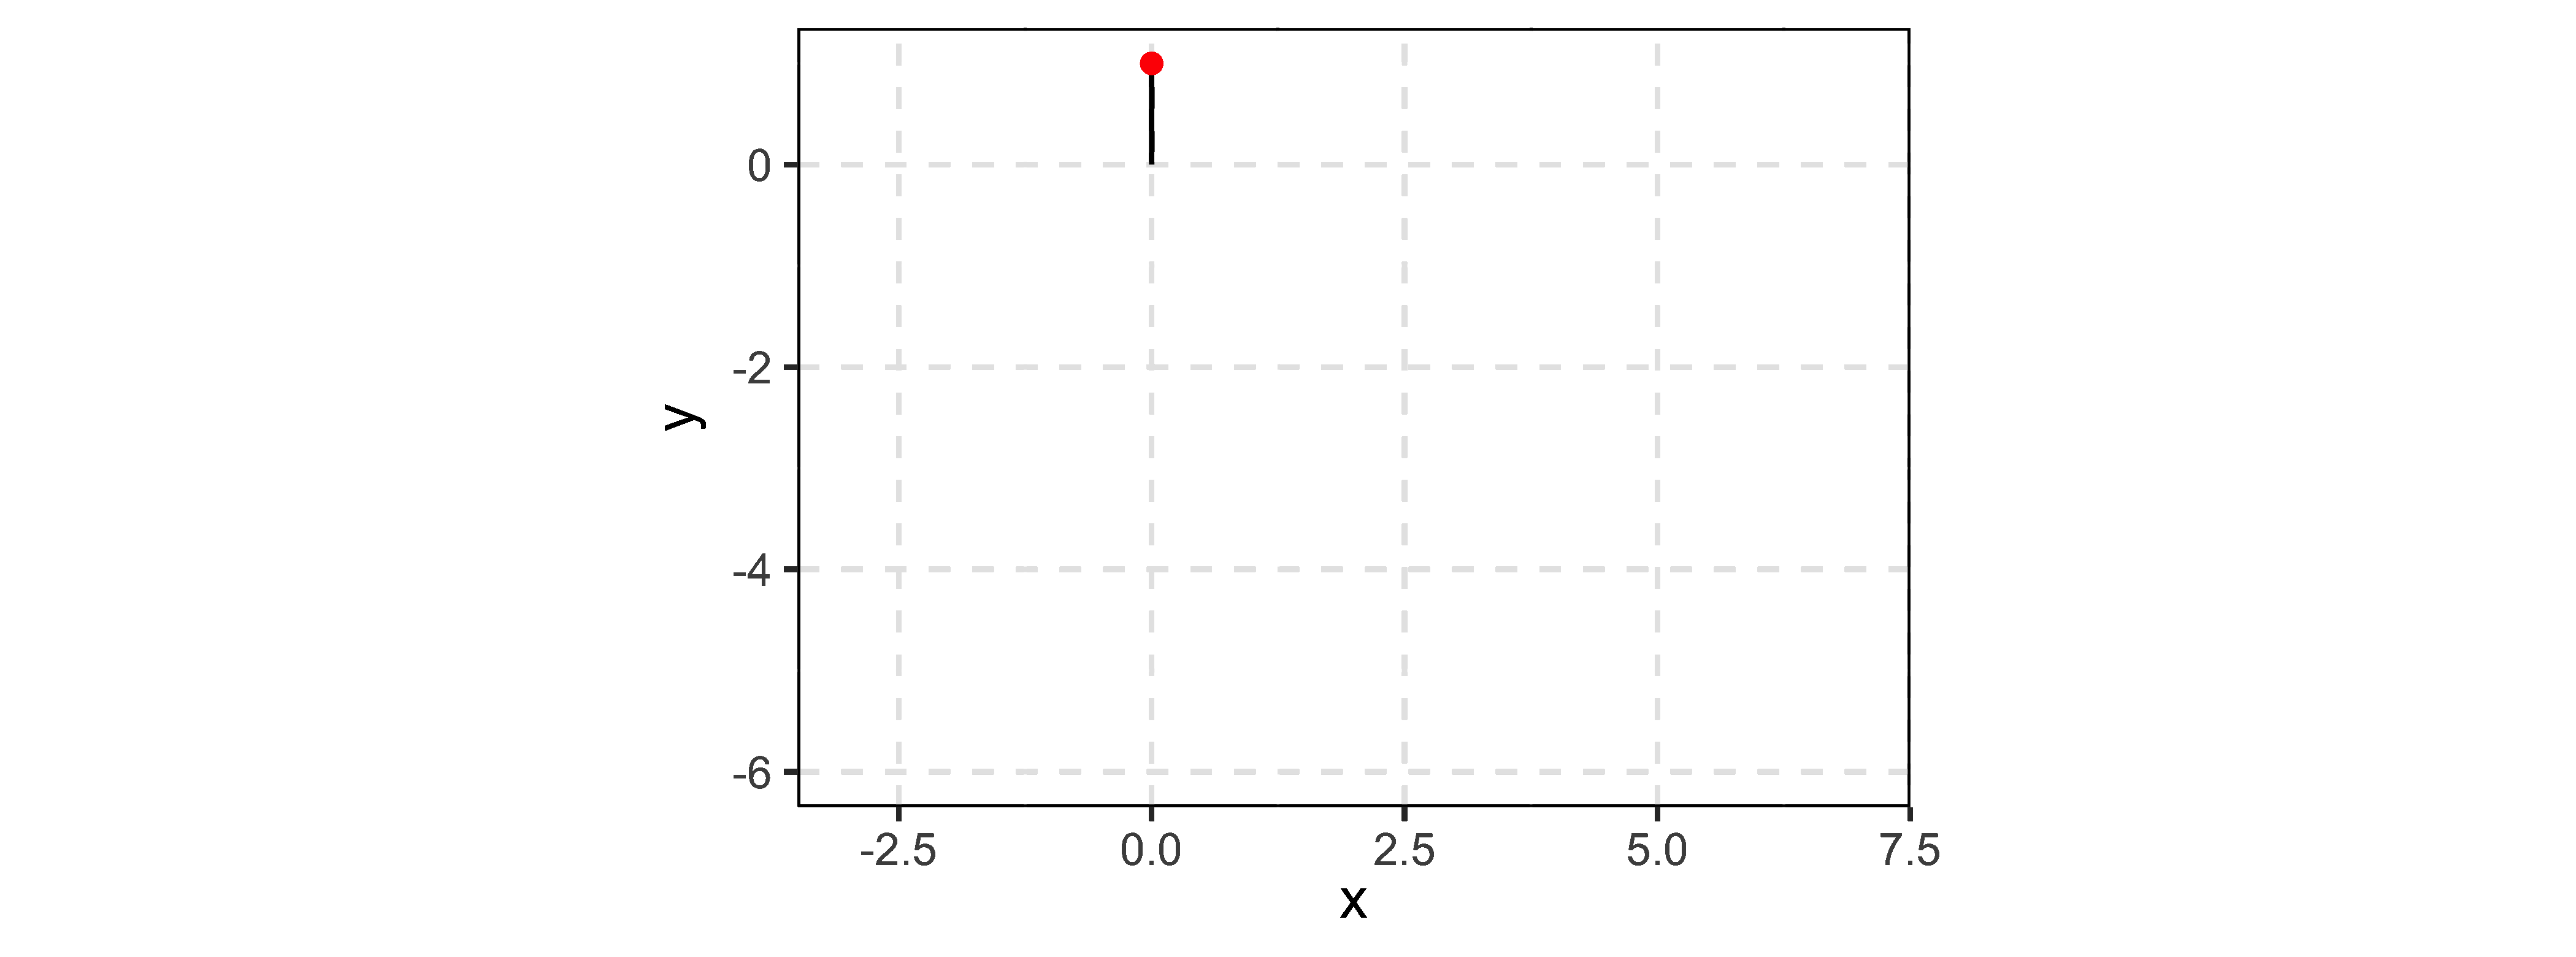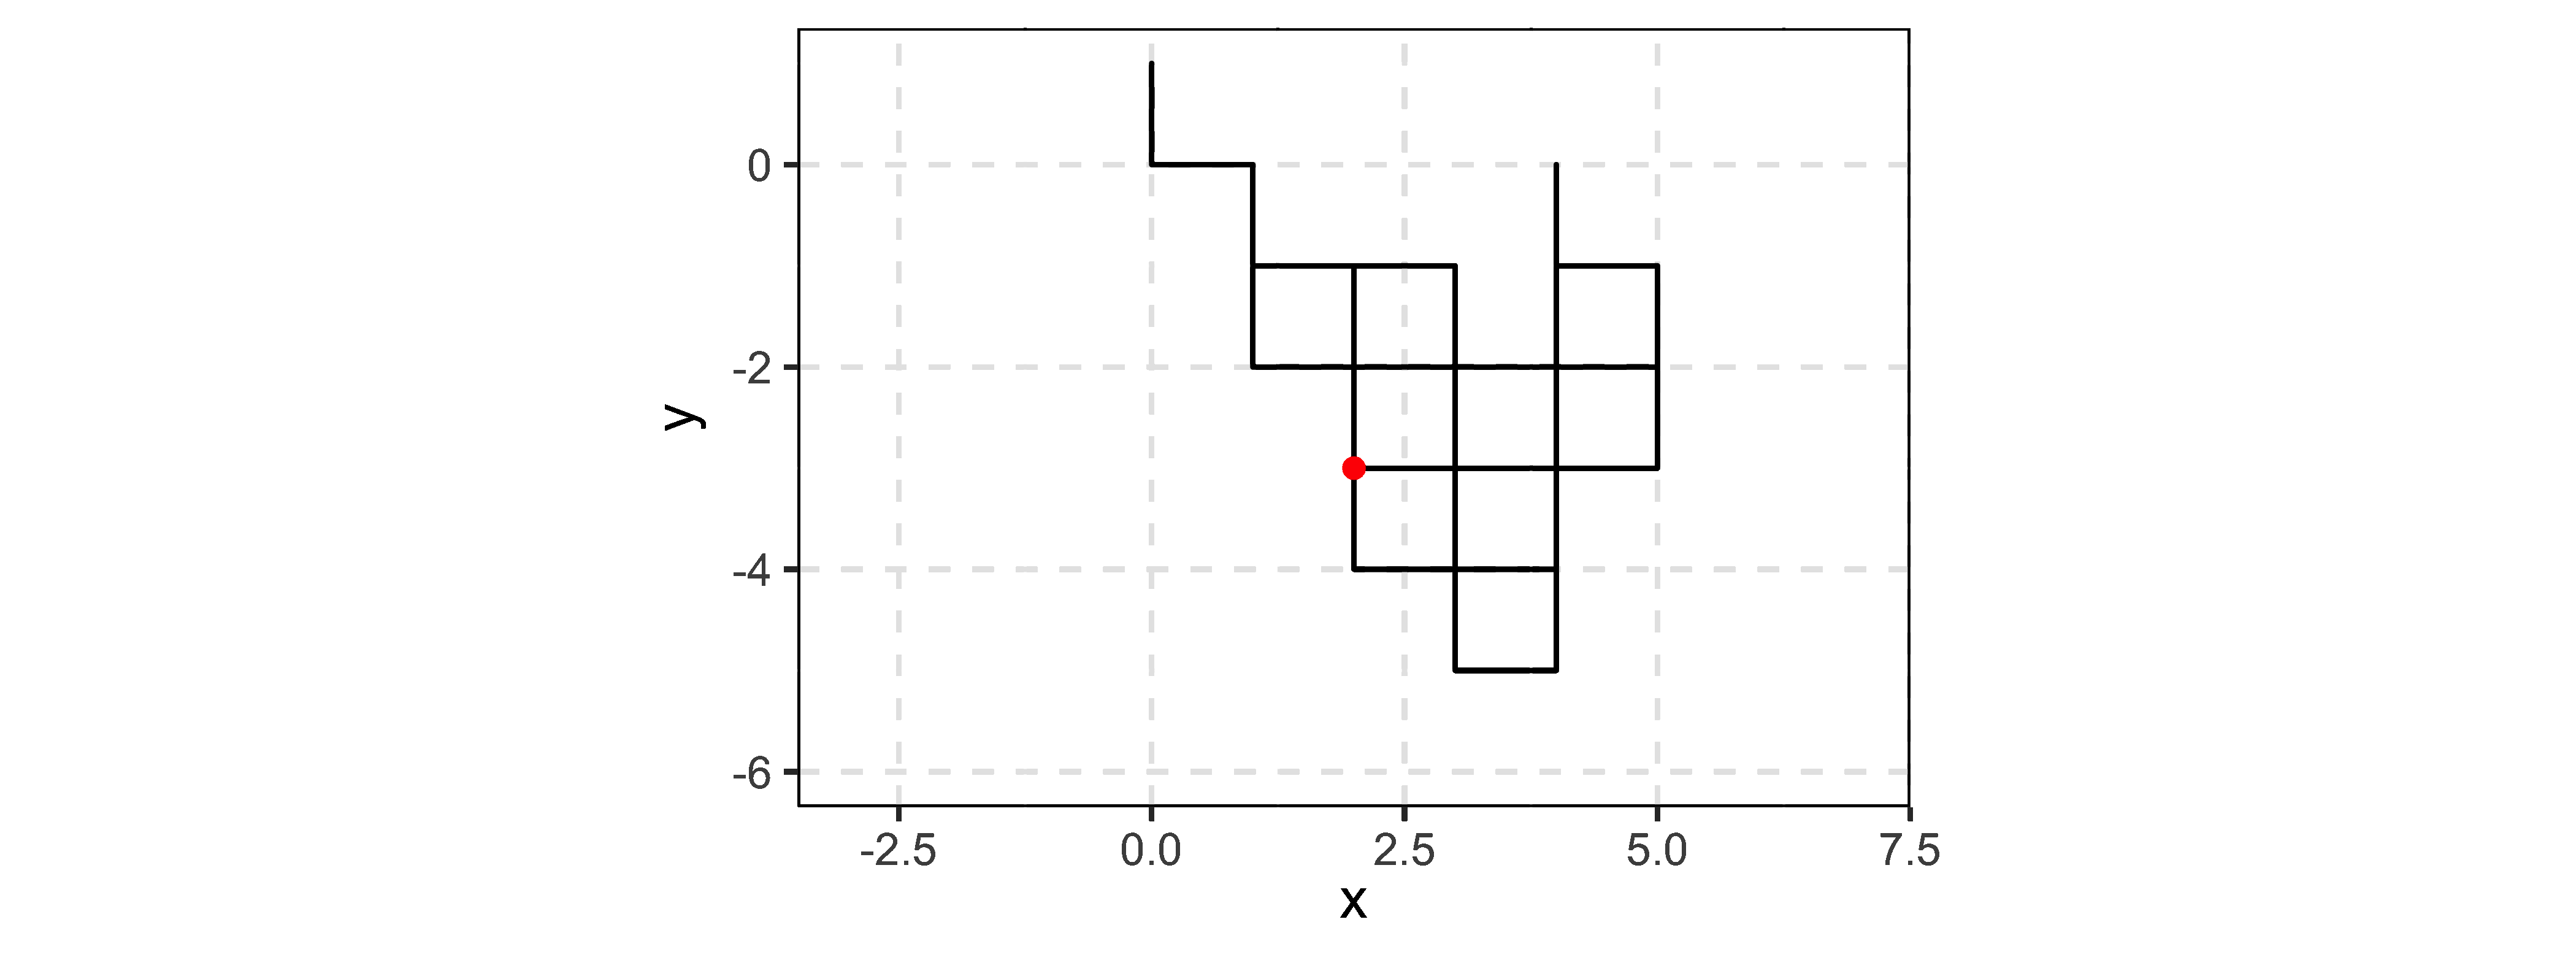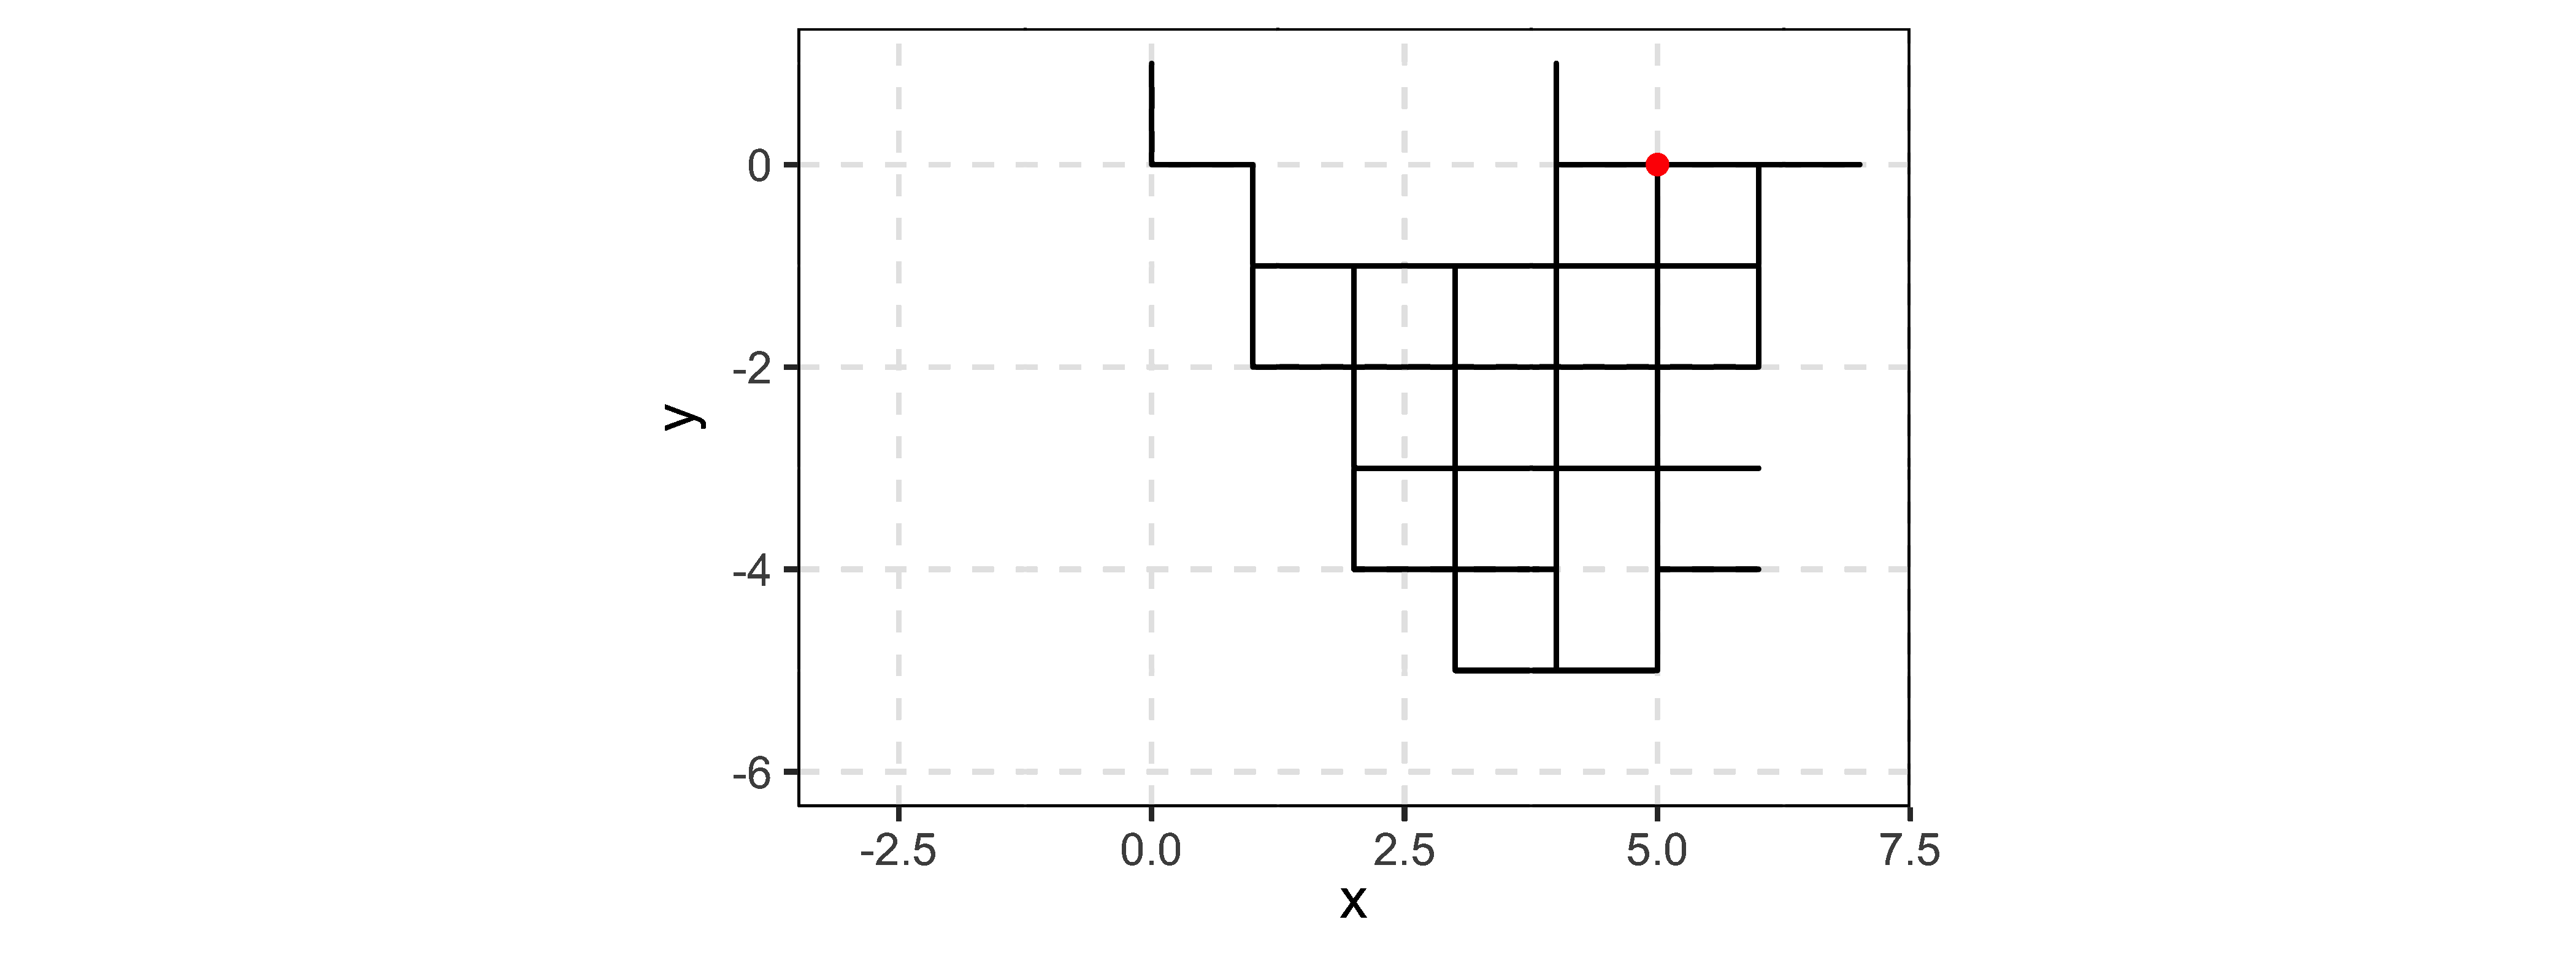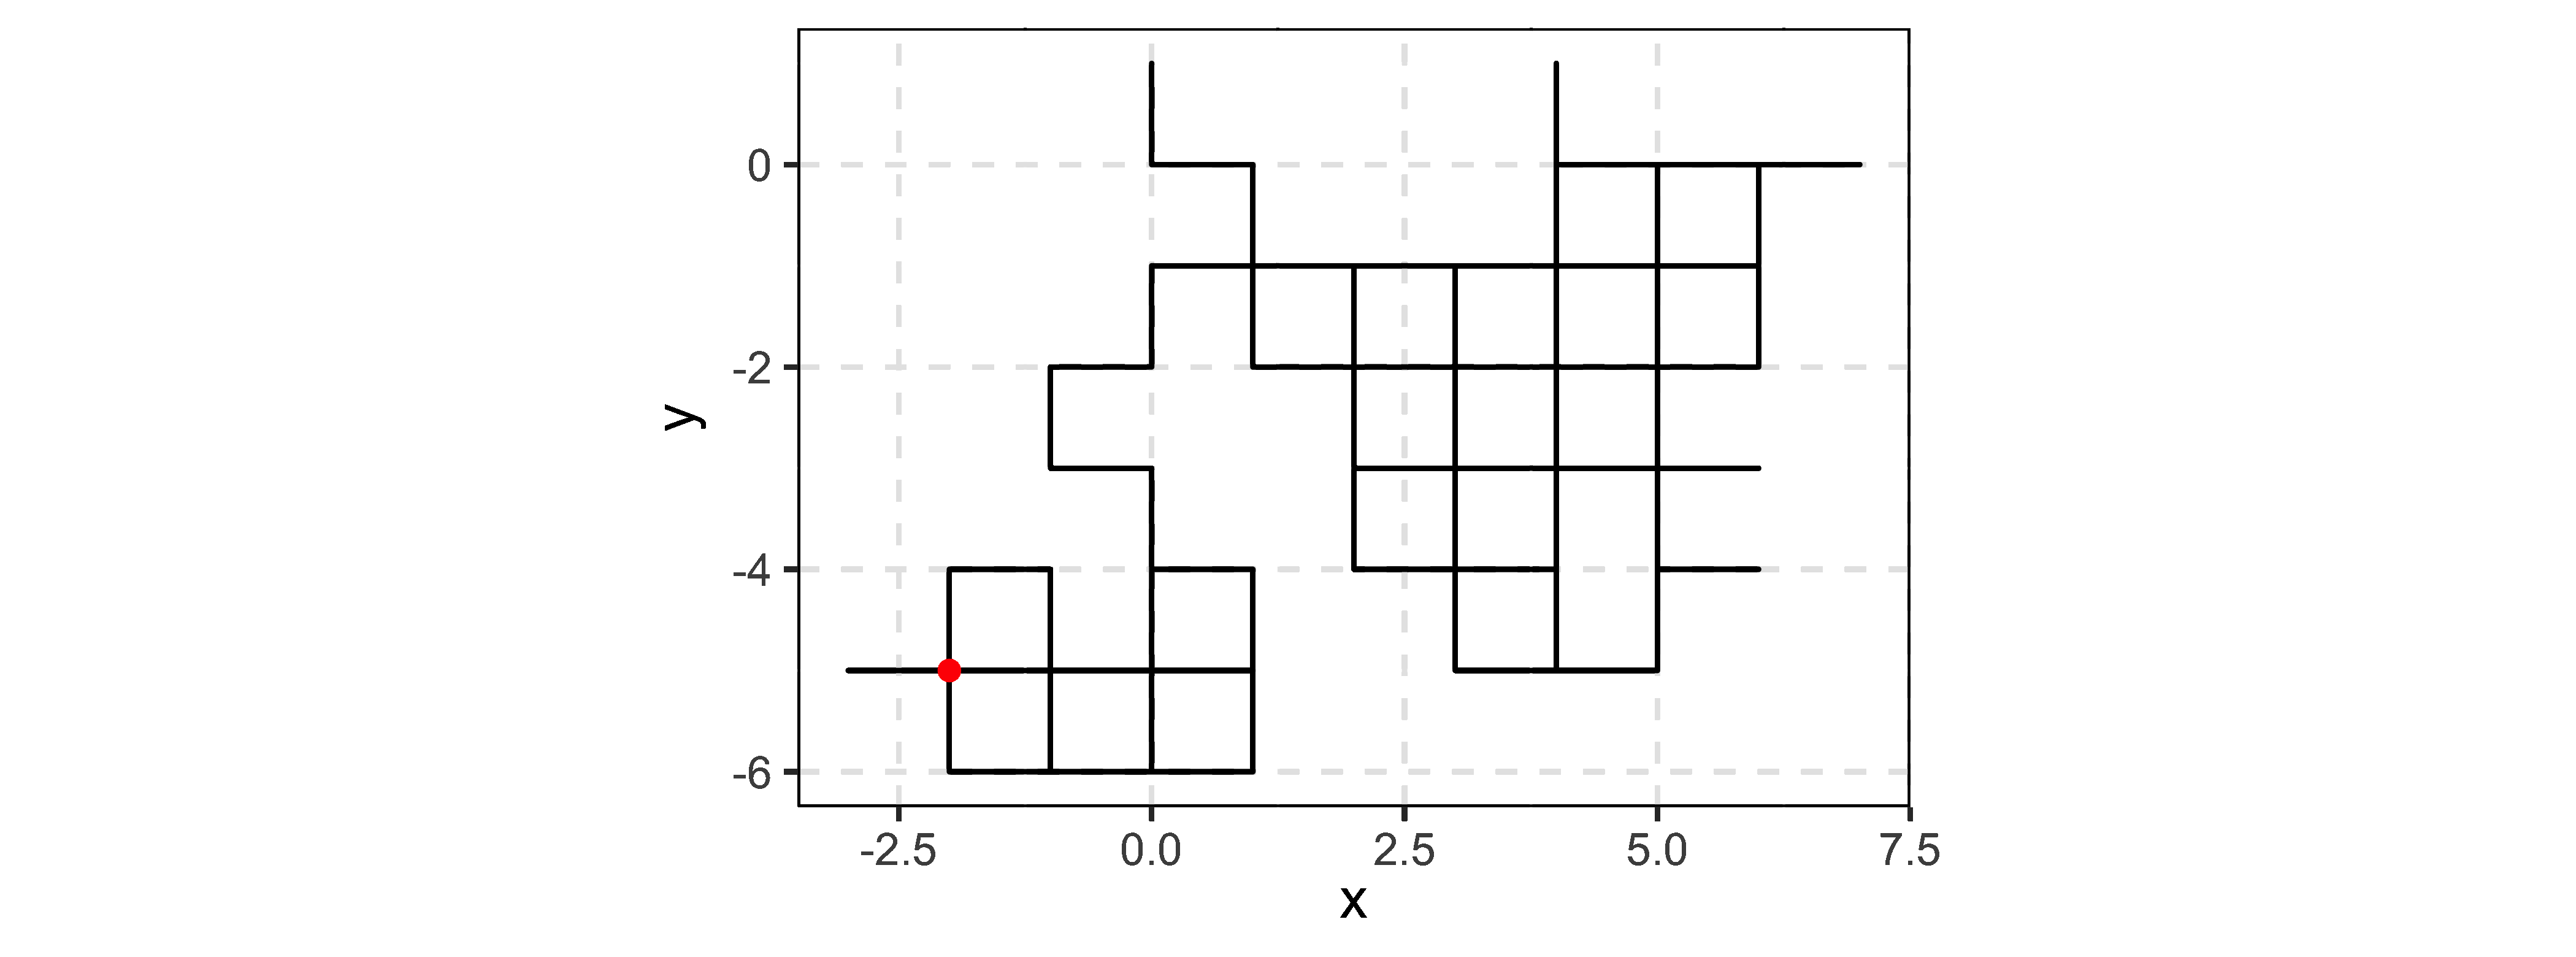
Example: 2-D random walk

Borrowed from Ross Ihaka’s online note.

  • A 2-D discrete random walk:
    • Start at the point (0, 0)
    • For t = 1, 2, \cdots, take a unit step in a randomly chosen direction
      • N, S, E, W

Naive implementation with a for loop

rw2d_loop <- function(n) {
  xpos <- rep(0, n)
  ypos <- rep(0, n)
  xdir <- c(TRUE, FALSE)
  step_size <- c(1, -1)
  for (i in 2:n) {
    if (sample(xdir, 1)) {
      xpos[i] <- xpos[i - 1] + sample(step_size, 1)
      ypos[i] <- ypos[i - 1]
    } else {
      xpos[i] <- xpos[i - 1]
      ypos[i] <- ypos[i - 1] + sample(step_size, 1)
    }
  }
  return(data.frame(x = xpos, y = ypos))
}

Vectorization without loops

rw2d_vec <- function(n) {
  xsteps <- c(-1, 1, 0, 0)
  ysteps <- c(0, 0, -1, 1)
  dir <- sample(1:4, n - 1, replace = TRUE)
  xpos <- c(0, cumsum(xsteps[dir]))
  ypos <- c(0, cumsum(ysteps[dir]))

  return(data.frame(x = xpos, y = ypos))
}

The trick: draw all n-1 directions in one call, then cumsum() the steps.

Comparison

n <- 100000
t0 <- Sys.time()
df <- rw2d_loop(n)
cat("Naive implementation: ", difftime(Sys.time(), t0, units = "secs"))
## Naive implementation:  0.3029308
t0 <- Sys.time()
df2 <- rw2d_vec(n)
cat("Vectorized implementation: ", difftime(Sys.time(), t0, units = "secs"))
## Vectorized implementation:  0.001620054

Two orders of magnitude, for the same random walk.

Example: standard error under heteroskedasticity

In a linear regression model with heteroskedasticity, the asymptotic distribution of the OLS estimator is

\sqrt{n}\left(\widehat{\beta}-\beta_0\right) \stackrel{d}{\rightarrow} N\left(0, E\left[x_i x_i^{\prime}\right]^{-1} \operatorname{var}\left(x_i e_i\right) E\left[x_i x_i^{\prime}\right]^{-1}\right)

where \operatorname{var}\left(x_i e_i\right) is estimated by

\frac{1}{n} \sum^n_{i=1} x_i x_i^{\prime} \widehat{e}_i^2=\frac{1}{n} X^{\prime} D X=\frac{1}{n}\left(X^{\prime} D^{1 / 2}\right)\left(D^{1 / 2} X\right)

and D is a diagonal matrix of \left(\widehat{e}_1^2, \widehat{e}_{2}^2, \ldots, \widehat{e}_n^2\right).

Four routes to the same matrix

  1. Literally sum \hat{e}_i^2 x_i x_i^{\prime}
  2. Compute X^{\prime} D X with a dense central matrix
  3. Compute X^{\prime} D X with a sparse central matrix
  4. Do a cross product on X\hat{e}, taking advantage of element-by-element operations in R

Mathematically identical. Computationally, not at all.

A linear probability model

Consider a linear probability model in which the outcome variable takes binary values \{0, 1\},

y_i = x_i^\prime \beta + v_i, \qquad \text{with } \mathbb{E} \left(v_i \vert x_i \right) = 0,

which implies

\mathbb{E}\left( y_i \vert x_i \right) = \mathrm{Pr} \left( y_i = 1 \right) = x_i^\prime \beta.

A linear probability model (cont.)

Note that v_i = \begin{cases} 1 - x_i^\prime \beta & y_i = 1 \\ - x_i^\prime\beta & y_i = 0 \end{cases}, and therefore

\mathrm{var} \left(v_i \vert x_i \right) = x_i^\prime\beta \left(1 - x_i^\prime\beta\right).

The error term is heteroskedastic.

DGP and OLS estimation

lpm <- function(n) {
  # set the parameters
  b0 <- matrix(c(-1, 1), nrow = 2)

  # generate the data from a Probit model
  e <- rnorm(n)
  X <- cbind(1, rnorm(n))
  Y <- as.numeric(X %*% b0 + e >= 0)
  # note that in this regression bhat does not converge to b0
  # because the model is mis-specified

  # OLS estimation
  bhat <- solve(t(X) %*% X, t(X) %*% Y)
  e_hat <- Y - X %*% bhat
  return(list(X = X, e_hat = as.vector(e_hat)))
}

Set up

# Set up
n <- 50
Rep <- 1000
data.Xe <- lpm(n)
X <- data.Xe$X
e_hat <- data.Xe$e_hat

The four implementations

# Estimation
est_func <- function(X, e_hat, opt) {
  if (opt == 1) {
    for (i in 1:n) {
      XXe2 <- matrix(0, nrow = 2, ncol = 2)
      XXe2 <- XXe2 + e_hat[i]^2 * X[i, ] %*% t(X[i, ])
    }
  } else if (opt == 2) {
    e_hat2_M <- matrix(0, nrow = n, ncol = n)
    diag(e_hat2_M) <- e_hat^2
    XXe2 <- t(X) %*% e_hat2_M %*% X
  } else if (opt == 3) {
    e_hat2_M <- Matrix::Matrix(0, ncol = n, nrow = n)
    diag(e_hat2_M) <- e_hat^2
    XXe2 <- t(X) %*% e_hat2_M %*% X
  } else if (opt == 4) {
    Xe <- X * e_hat
    XXe2 <- t(Xe) %*% Xe
  }

  XX_inv <- solve(t(X) %*% X)
  sig_B <- XX_inv %*% XXe2 %*% XX_inv
  return(sig_B)
}

Compare the speed, small sample

# Compare the speed
for (opt in 1:4) {
  pts0 <- Sys.time()
  for (iter in 1:Rep) {
    sig_B <- est_func(X, e_hat, opt)
  }
  cat("n =", n, ", Rep =", Rep, ", opt =", opt, ", time =", Sys.time() - pts0, "\n")
}
## n = 50 , Rep = 1000 , opt = 1 , time = 0.09427094 
## n = 50 , Rep = 1000 , opt = 2 , time = 0.01588511 
## n = 50 , Rep = 1000 , opt = 3 , time = 0.1466908 
## n = 50 , Rep = 1000 , opt = 4 , time = 0.006877184

Increase the sample size

n <- 2000
data.Xe <- lpm(n)
X <- data.Xe$X
e_hat <- data.Xe$e_hat
for (opt in 1:4) {
  pts0 <- Sys.time()
  for (iter in 1:Rep) {
    sig_B <- est_func(X, e_hat, opt)
  }
  cat("n =", n, ", Rep =", Rep, ", opt =", opt, ", time =", Sys.time() - pts0, "\n")
}
## n = 2000 , Rep = 1000 , opt = 1 , time = 2.929544 
## n = 2000 , Rep = 1000 , opt = 2 , time = 18.82715 
## n = 2000 , Rep = 1000 , opt = 3 , time = 0.174623 
## n = 2000 , Rep = 1000 , opt = 4 , time = 0.02905297

What the timings teach us

  • Option 4, the cross product t(Xe) %*% Xe, wins at both sample sizes. Element-by-element operations in R are cheap.
  • Option 2 stores an n \times n dense matrix that is almost entirely zeros. Fine at n = 50, disastrous at n = 2000.
  • Option 3 stores the same matrix sparsely. The bookkeeping overhead does not pay off at n = 50, but it scales.
  • The ranking of implementations is not invariant to sample size. Always profile at the scale you actually work at.

Parallel loops

We can exploit the power of multicore machines to speed up loops by parallel computing. The packages foreach and doParallel are useful for this.

capture <- function() {
  x <- rpois(sample_size, mu)
  bounds <- CI(x)
  return(((bounds$lower <= mu) & (mu <= bounds$upper)))
}

# Workhorse packages
library(foreach)
library(doParallel)

Rep <- 100000
sample_size <- 1000

registerDoParallel(8) # open 8 CPUs to accept incoming jobs.

Many small jobs

pts0 <- Sys.time() # check time
out <- foreach(icount(Rep), .combine = c) %dopar% {
  x <- rpois(sample_size, mu)
  bounds <- CI(x)
  ((bounds$lower <= mu) & (mu <= bounds$upper))
}
cat("parallel loop takes", Sys.time() - pts0, "seconds\n")
## parallel loop takes 3.264464 seconds
pts0 <- Sys.time() # check time
out <- foreach(icount(Rep), .combine = c) %do% {
  x <- rpois(sample_size, mu)
  bounds <- CI(x)
  ((bounds$lower <= mu) & (mu <= bounds$upper))
}
cat("sequential loop takes", Sys.time() - pts0, "seconds\n")
## sequential loop takes 5.996085 seconds

Fewer, bigger jobs

We change the nature of the task a bit: 200 replications of a much larger sample.

Rep <- 200
sample_size <- 200000

pts0 <- Sys.time() # check time
out <- foreach(icount(Rep), .combine = c) %dopar% {
  x <- rpois(sample_size, mu)
  bounds <- CI(x)
  ((bounds$lower <= mu) & (mu <= bounds$upper))
}
cat("parallel loop takes", Sys.time() - pts0, "seconds\n")
## parallel loop takes 0.147933 seconds
pts0 <- Sys.time() # check time
out <- foreach(icount(Rep), .combine = c) %do% {
  x <- rpois(sample_size, mu)
  bounds <- CI(x)
  ((bounds$lower <= mu) & (mu <= bounds$upper))
}
cat("sequential loop takes", Sys.time() - pts0, "seconds\n")
## sequential loop takes 0.8356161 seconds

Reading the two timings

  • Eight CPUs never buy you an eight-fold speedup. Every job has to be shipped to a worker and its result shipped back.
  • With 100,000 tiny jobs that overhead is paid 100,000 times, and it eats a large share of the gain.
  • With 200 expensive jobs the overhead is paid 200 times and is negligible next to the computation, so the speedup is much closer to the ideal.

Note

For more details on parallel computing, see the lecture notes by Grant McDermott and the references therein.

Functional programming

Loops can run very slowly, and an inconspicuous for loop has been known to bring an entire analysis crashing to its knees.1

The bigger problem with for loops, however, is that they deviate from the norms and best practices of functional programming.

What is functional programming?

Functional programming (FP) is arguably the most important thing you can take away from today’s lecture. Hadley Wickham puts the core idea like this in Advanced R:

R, at its heart, is a functional programming (FP) language. […] R has what’s known as first class functions.

You can do anything with a function that you can do with a vector:

  • assign it to a variable,
  • store it in a list,
  • pass it as an argument to another function,
  • create it inside a function,
  • return it as the result of a function.

Hadley explains it better

Why not for loops?

Summary: for loops emphasise the objects we are working with (say, a vector of numbers) rather than the operations we want to apply to them (get the mean, or the median, or whatever).

  • This is inefficient: it requires us to write out the for loop by hand rather than getting an R function to create the loop for us.
  • As a corollary, for loops pollute our global environment with counting variables. Look at your “Environment” pane: i is sitting there, equal to the last value of its loop.

Creating those auxiliary variables is almost certainly not an intended outcome, and they can cause errors when we inadvertently refer to a similarly-named variable elsewhere in our script. So we best remove them as soon as we are finished.

rm(i)

Why not for loops? (cont.)

Another annoyance arrived in cases where we want to “grow” an object as we iterate over it. To do that with a for loop, we had to create an empty object first.

FP lets us avoid the explicit loop construct and its associated downsides. In practice, there are two ways to implement FP in R:

  1. The *apply family of functions in base R.
  2. The map*() family of functions from purrr.

Let’s explore these in more depth.

1) lapply()

Its syntax closely mimics the syntax of a basic for-loop.

# for(i in 1:10) print(LETTERS[i]) ## Our original for loop (for comparison)
lapply(1:10, function(i) LETTERS[i])
## [[1]]
## [1] "A"
## 
## [[2]]
## [1] "B"
## 
## [[3]]
## [1] "C"
## 
## [[4]]
## [1] "D"
## 
## [[5]]
## [1] "E"
## 
## [[6]]
## [1] "F"
## 
## [[7]]
## [1] "G"
## 
## [[8]]
## [1] "H"
## 
## [[9]]
## [1] "I"
## 
## [[10]]
## [1] "J"

Three things to notice

  1. No i in your global environment. Because of R’s lexical scoping rules, any object created and invoked by a function is evaluated in a sandbox outside your global environment.
  2. The syntax barely changed when switching from for() to lapply(). The essential structure is the same: first the iteration list (1:10), then the desired function or operation (LETTERS[i]).
  3. The returned object is a list. lapply() accepts vectors, data frames and lists as arguments, but always returns a list, with one element per iteration of the loop. (So now you know where the “l” in “lapply” comes from.)

Getting output that is not a list

Several options exist.1 The one I use most commonly is to bind the list elements into a single data frame with dplyr::bind_rows() or data.table::rbindlist().

lapply(1:10, function(i) {
  df <- tibble(num = i, let = LETTERS[i])
  return(df)
}) %>%
  bind_rows()
## # A tibble: 10 × 2
##      num let  
##    <int> <chr>
##  1     1 A    
##  2     2 B    
##  3     3 C    
##  4     4 D    
##  5     5 E    
##  6     6 F    
##  7     7 G    
##  8     8 H    
##  9     9 I    
## 10    10 J

1 E.g. pipe the output to unlist() if you want a vector, or use sapply(), which is covered next.

Why lapply() anyway?

The default list-return behaviour may not sound ideal at first, but I use lapply() more frequently than any of the other apply family members.

  • My functions normally return multiple objects of different type, which makes a list the only sensible format;
  • or they return a single data frame, which is where dplyr::bind_rows() and data.table::rbindlist() come in.

The *apply family: sapply()

sapply() stands for “simplify apply”. It is essentially a wrapper around lapply that tries to return simplified output that matches the input type. Feed it a vector and it will try to return a vector.

sapply(1:10, function(i) LETTERS[i])
##  [1] "A" "B" "C" "D" "E" "F" "G" "H" "I" "J"

The *apply family: apply()

apply() applies functions over array margins: the rows or columns of matrices and data frames.

# Create a simple matrix
mat <- matrix(1:12, nrow = 3, ncol = 4)
print(mat)
##      [,1] [,2] [,3] [,4]
## [1,]    1    4    7   10
## [2,]    2    5    8   11
## [3,]    3    6    9   12
apply(mat, 2, mean) ## apply mean over columns
## [1]  2  5  8 11
apply(mat, 1, mean) ## apply mean over rows
## [1] 5.5 6.5 7.5

For a concise overview of the different *apply() functions, see this blog post by Neil Saunders.

2) The purrr package

purrr’s map() is the tidyverse’s lapply(). Same syntax, same list output:

map(1:10, function(i) { ## only need to swap `lapply` for `map`
  df <- tibble(num = i, let = LETTERS[i])
  return(df)
})
## [[1]]
## # A tibble: 1 × 2
##     num let  
##   <int> <chr>
## 1     1 A    
## 
## [[2]]
## # A tibble: 1 × 2
##     num let  
##   <int> <chr>
## 1     2 B    
## 
## [[3]]
## # A tibble: 1 × 2
##     num let  
##   <int> <chr>
## 1     3 C    
## 
## [[4]]
## # A tibble: 1 × 2
##     num let  
##   <int> <chr>
## 1     4 D    
## 
## [[5]]
## # A tibble: 1 × 2
##     num let  
##   <int> <chr>
## 1     5 E    
## 
## [[6]]
## # A tibble: 1 × 2
##     num let  
##   <int> <chr>
## 1     6 F    
## 
## [[7]]
## # A tibble: 1 × 2
##     num let  
##   <int> <chr>
## 1     7 G    
## 
## [[8]]
## # A tibble: 1 × 2
##     num let  
##   <int> <chr>
## 1     8 H    
## 
## [[9]]
## # A tibble: 1 × 2
##     num let  
##   <int> <chr>
## 1     9 I    
## 
## [[10]]
## # A tibble: 1 × 2
##     num let  
##   <int> <chr>
## 1    10 J

map_df(): pick your output type

map() comes with its own variants for returning objects of a desired type. purrr::map_df() returns a data frame:

map_df(1:10, function(i) { ## don't need bind_rows with `map_df`
  df <- tibble(num = i, let = LETTERS[i])
  return(df)
})
## # A tibble: 10 × 2
##      num let  
##    <int> <chr>
##  1     1 A    
##  2     2 B    
##  3     3 C    
##  4     4 D    
##  5     5 E    
##  6     6 F    
##  7     7 G    
##  8     8 H    
##  9     9 I    
## 10    10 J

More efficient, i.e. less typing, than the lapply() version: no extra row-binding step at the end. Jenny Bryan’s purrr tutorial goes much deeper.

Create and iterate over named functions

We can split the function and the iteration (and binding) into separate steps. This is generally a good idea, since you typically create named functions with the goal of reusing them.

## Create a named function
num_to_alpha <-
  function(i) {
    df <- tibble(num = i, let = LETTERS[i])
    return(df)
  }

Create and iterate over named functions (cont.)

Now we can easily iterate over our function using different input values.

lapply(1:10, num_to_alpha) %>%
  bind_rows()
## # A tibble: 10 × 2
##      num let  
##    <int> <chr>
##  1     1 A    
##  2     2 B    
##  3     3 C    
##  4     4 D    
##  5     5 E    
##  6     6 F    
##  7     7 G    
##  8     8 H    
##  9     9 I    
## 10    10 J
map_df(c(1, 5, 26, 3), num_to_alpha)
## # A tibble: 4 × 2
##     num let  
##   <dbl> <chr>
## 1     1 A    
## 2     5 E    
## 3    26 Z    
## 4     3 C

Iterate over multiple inputs

Thus far we have fed our functions a single input when iterating. What if we want to iterate over multiple inputs? Consider a function that takes x and y, combines them in a data frame, and uses them to create a third variable z.

## Create a named function
multi_func <-
  function(x, y) {
    df <-
      tibble(x = x, y = y) %>%
      mutate(z = (x + y) / sqrt(x))
    return(df)
  }

Another silly function that we could easily improve upon with standard vectorised tools. The goal is to demonstrate programming principles with simple examples that carry over to complicated cases where vectorisation is not possible.

Test it before iterating

multi_func(1, 6)
## # A tibble: 1 × 3
##       x     y     z
##   <dbl> <dbl> <dbl>
## 1     1     6     7

Great, it works. Two basic approaches let us iterate over various levels of both x and y:

  1. Use base::mapply() or purrr::pmap().
  2. Use a data frame of input combinations.

1) mapply() and pmap()

Both base R, through mapply(), and purrr, through pmap(), handle multiple inputs. The latter is easier to work with, since its syntax is nearly identical to the single-input case.

## Note that the inputs are now moved to the *end* of the call.
## Also, mapply() is based on sapply(), so we also have to tell it not to
## simplify if we want to keep the list structure.
mapply(
  multi_func,
  x = 1:5, ## Our "x" vector input
  y = 6:10, ## Our "y" vector input
  SIMPLIFY = FALSE ## Tell it not to simplify to keep the list structure
) %>%
  bind_rows()
## # A tibble: 5 × 3
##       x     y     z
##   <int> <int> <dbl>
## 1     1     6  7   
## 2     2     7  6.36
## 3     3     8  6.35
## 4     4     9  6.5 
## 5     5    10  6.71

1) mapply() and pmap() (cont.)

Second, purrr::pmap():

## Note that the inputs are combined in a list.
pmap_df(list(x = 1:5, y = 6:10), multi_func)
## # A tibble: 5 × 3
##       x     y     z
##   <int> <int> <dbl>
## 1     1     6  7   
## 2     2     7  6.36
## 3     3     8  6.35
## 4     4     9  6.5 
## 5     5    10  6.71

2) Using a data frame of input combinations

Both approaches above work perfectly well, but in practice I prefer to “cheat” by feeding a multi-input function a single data frame that specifies the necessary combination of variables by row. Why?

  • Length safety. No accidentally feeding separate inputs of different lengths. Try the above with an x input of 1:10, everything else unchanged: pmap() at least fails with a helpful message, but mapply() completes with totally misaligned columns. A rectangular data frame forces equal lengths a priori.
  • All combinations. I often need to run a function over all possible combinations of inputs, so it is convenient to use that data frame directly.1
  • Simplicity. One input is simpler and cleaner. This matters most with complicated functions that nest heavily and/or parallelize.

1 base::expand.grid(), and the equivalent tidyr::expand_grid() and data.table::CJ(), automatically generate a data frame of all combinations.

2) Using a data frame of input combinations (cont.)

parent_func <-
  ## Main function: Takes a single data frame as an input
  function(input_df) {
    df <-
      ## Nested iteration function
      map_df(
        1:nrow(input_df), ## i.e. Iterate (map) over each row of the input data frame
        function(n) {
          ## Extract the `x` and `y` values from row "n" of the data frame
          x <- input_df$x[n]
          y <- input_df$y[n]
          ## Use the extracted values
          df <- multi_func(x, y)
          return(df)
        }
      )
    return(df)
  }

Three conceptual steps

  1. Create a new function parent_func(), which takes a single input: a data frame containing x and y columns (and potentially other columns too).
  2. This input data frame is passed to a second, nested function, which iterates over the rows of the data frame.
  3. During each iteration, the x and y values for that row are passed to our original multi_func(), which returns a data frame containing the desired output.

Test it with two input data frames

## Case 1: Iterate over x=1:5 and y=6:10
input_df1 <- tibble(x = 1:5, y = 6:10)
parent_func(input_df1)
## # A tibble: 5 × 3
##       x     y     z
##   <int> <int> <dbl>
## 1     1     6  7   
## 2     2     7  6.36
## 3     3     8  6.35
## 4     4     9  6.5 
## 5     5    10  6.71
## Case 2: Iterate over *all possible
## combinations* of x=1:5 and y=6:10
input_df2 <- expand.grid(x = 1:5, y = 6:10)
parent_func(input_df2)
## # A tibble: 25 × 3
##        x     y     z
##    <int> <int> <dbl>
##  1     1     6  7   
##  2     2     6  5.66
##  3     3     6  5.20
##  4     4     6  5   
##  5     5     6  4.92
##  6     1     7  8   
##  7     2     7  6.36
##  8     3     7  5.77
##  9     4     7  5.5 
## 10     5     7  5.37
## # ℹ 15 more rows

Revisit the (parallel) loop example

We implemented the confidence-interval simulation with a for loop. How about following the functional programming principles instead?

capture <- function(i) {
  x <- rpois(sample_size, mu)
  bounds <- CI(x)
  return(((bounds$lower <= mu) & (mu <= bounds$upper)))
}

mu <- 2
Rep <- 200
sample_size <- 200000

pts0 <- Sys.time()
out <- lapply(1:Rep, capture)
cat("sequential loop takes", Sys.time() - pts0, "seconds\n")
## sequential loop takes 0.814184 seconds

Parallelizing with future.apply

How to parallelize it? We use the future.apply package.

future::plan("multisession")
library(future.apply)
pts0 <- Sys.time()
out <- future_lapply(1:Rep, capture)
cat("parallel loop takes", Sys.time() - pts0, "seconds\n")
## parallel loop takes 0.137156 seconds

Two changes, and that is all:

  • tell R to run the iteration in parallel, i.e. plan(multisession);
  • slightly amend the lapply() call, i.e. future_lapply().

And for the purrr crowd

Prefer the purrr::map() family and feeling left out? Don’t worry: the furrr package has you covered.

  • Once again, the syntax for these parallel functions is very little changed from their serial versions.
  • Tell R you want things in parallel with plan(multisession), then amend the map call to future_map_dfr(). The extra “r” tells future to concatenate the data frames from each iteration by rows.

Note

For more details on parallel computing, see the lecture notes by Grant McDermott and the references therein.

Statistics


A language created by statisticians

R has elegant built-in statistical functions. Four prefixes go ahead of the name of a probability distribution:

  • p: probability, i.e. the CDF
  • d: density for a continuous random variable, or mass for a discrete one
  • q: quantile
  • r: random variable generator

Distribution names include norm (normal), chisq (\chi^2), t (t), weibull (Weibull), cauchy (Cauchy), binomial (binomial), pois (Poisson), to name a few.

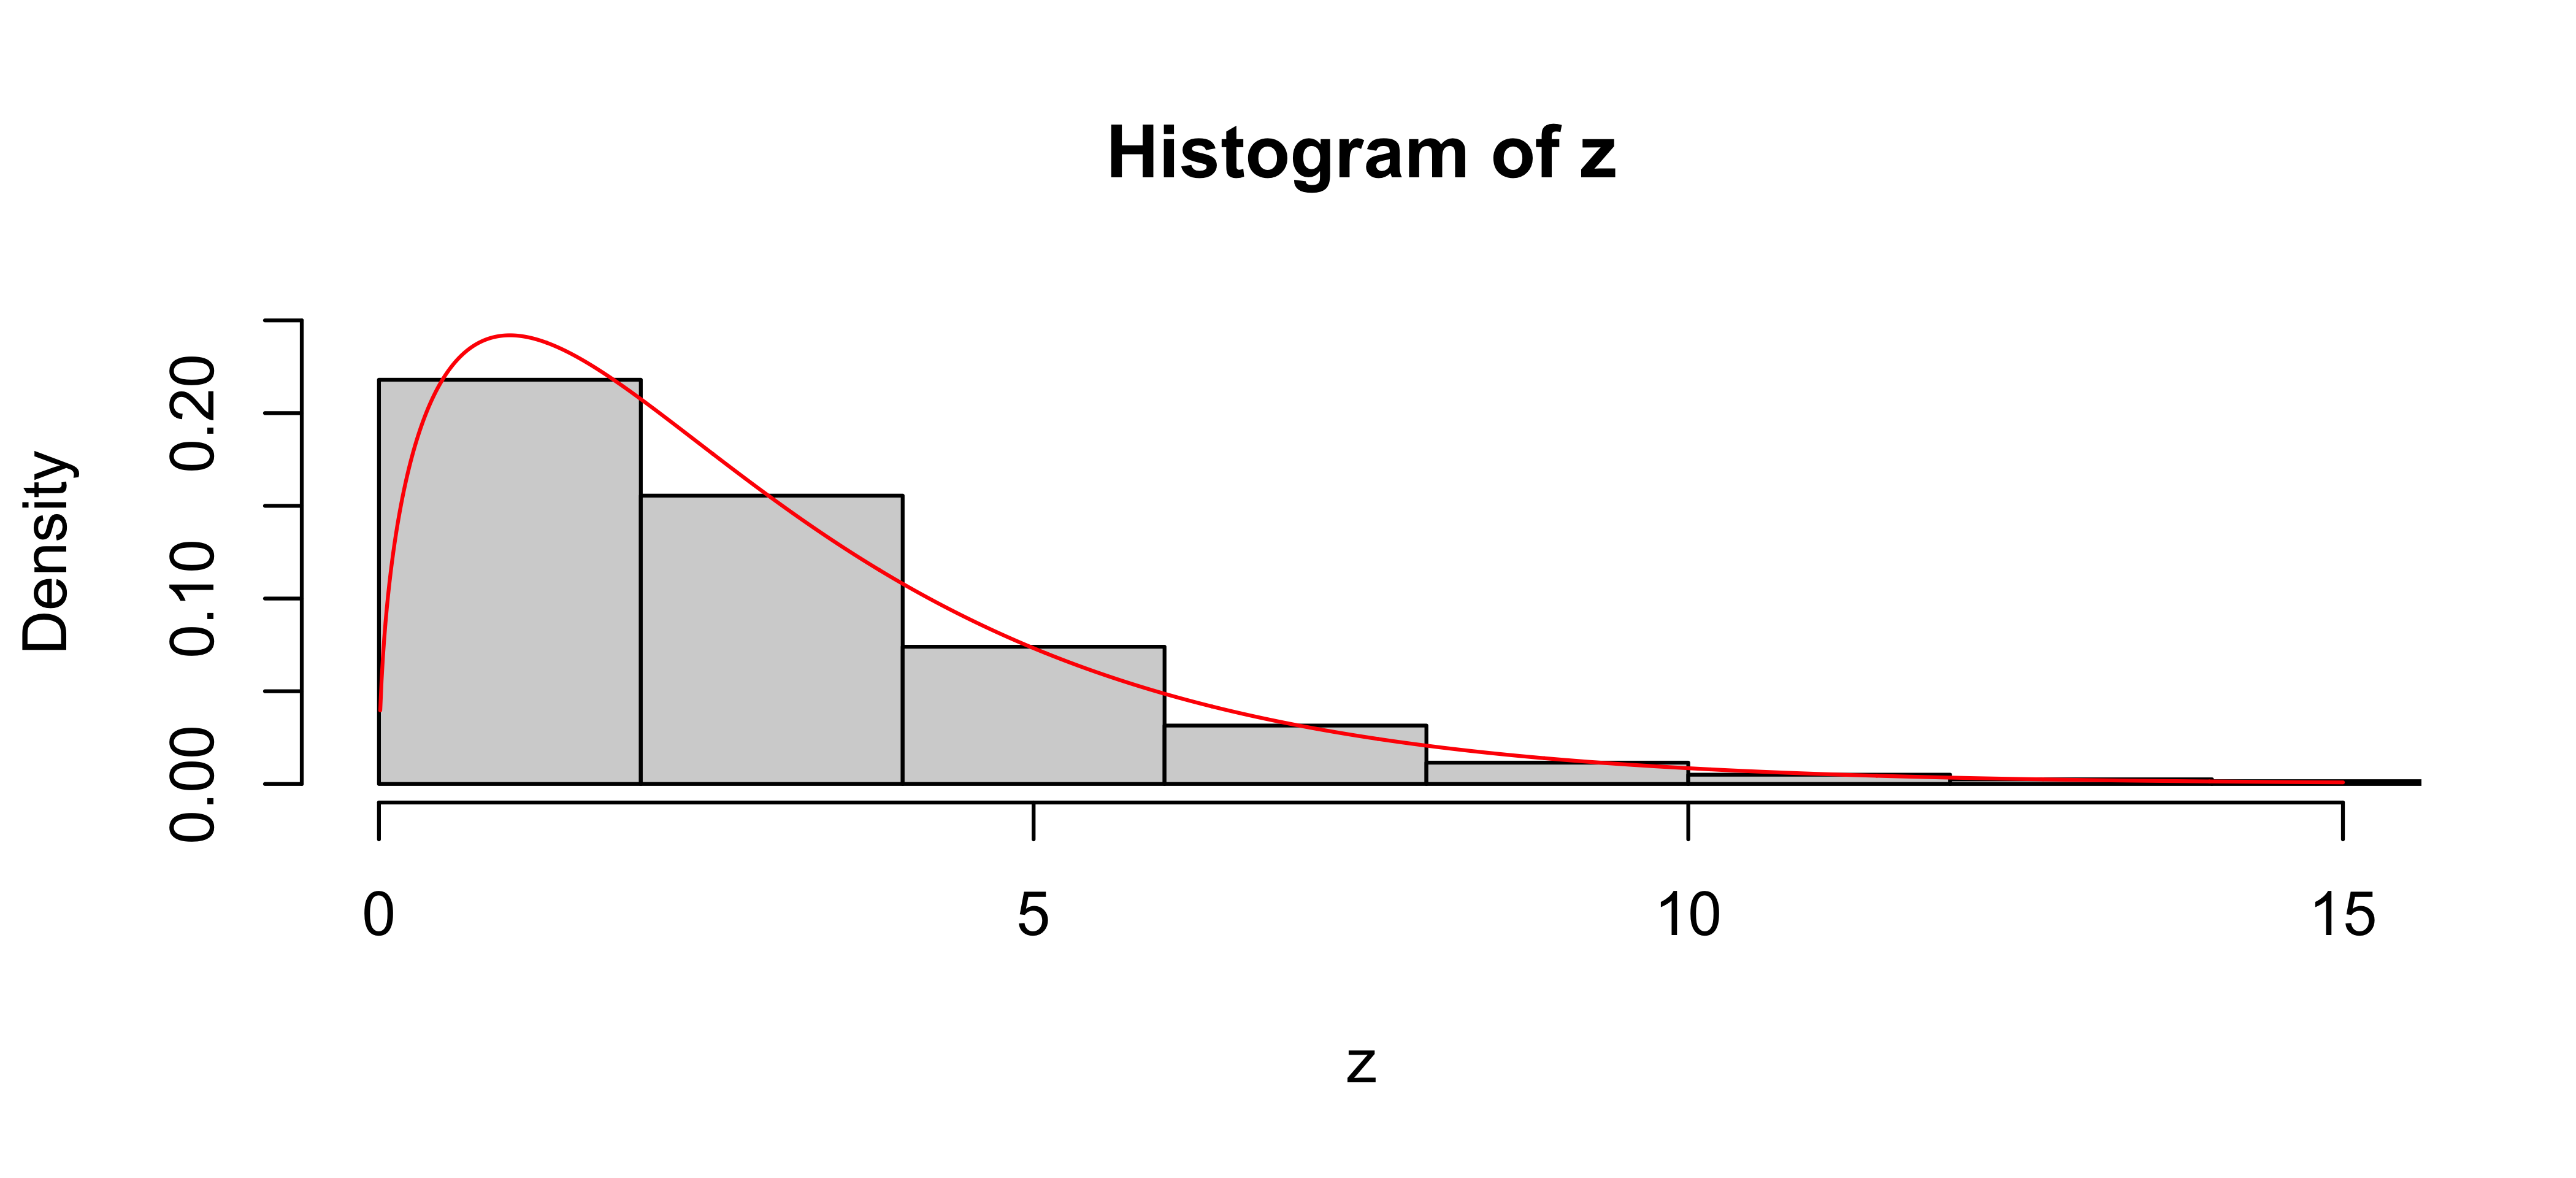
Example: sampling error

  1. Plot the density of \chi^2(3) over an equally spaced grid x_axis = seq(0.01, 15, by = 0.01).
  2. Generate 1000 observations from \chi^2(3) and plot their histogram.

The gap between the two is sampling error.

set.seed(100)
x_axis <- seq(0.01, 15, by = 0.01)
y <- dchisq(x_axis, df = 3)
z <- rchisq(1000, df = 3)

Example: sampling error (cont.)

hist(z, freq = FALSE, xlim = range(0.01, 15), ylim = range(0, 0.25))
lines(y = y, x = x_axis, type = "l", xlab = "x", ylab = "density", col = "red")

Statistical models: the formula interface

Statistical models are formulated as y ~ x:

  • y on the left-hand side is the dependent variable;
  • x on the right-hand side is the explanatory variable.

The built-in OLS function is lm, called as lm(y ~ x, data = data_frame).

All built-in regression functions in R share the same structure. Once one type of regression is understood, it is easy to extend to other regressions.

Linear models

# Linear models
n <- 100
x <- rnorm(n)
y <- 0.5 + 1 * x + rnorm(n)
result <- lm(y ~ x)

lm() does the estimation. summary() does the reporting.

summary() of a fitted model

summary(result)
## 
## Call:
## lm(formula = y ~ x)
## 
## Residuals:
##      Min       1Q   Median       3Q      Max 
## -2.49919 -0.53555 -0.08413  0.46672  2.74626 
## 
## Coefficients:
##             Estimate Std. Error t value Pr(>|t|)    
## (Intercept)  0.43953    0.09161   4.798 5.74e-06 ***
## x            1.03031    0.10158  10.143  < 2e-16 ***
## ---
## Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
## 
## Residual standard error: 0.9091 on 98 degrees of freedom
## Multiple R-squared:  0.5122, Adjusted R-squared:  0.5072 
## F-statistic: 102.9 on 1 and 98 DF,  p-value: < 2.2e-16

What is a fitted model object?

class(result)
## [1] "lm"
typeof(result)
## [1] "list"
result$coefficients
## (Intercept)           x 
##   0.4395307   1.0303095

An lm object is just a list carrying a class attribute. Everything summary() prints is computed from its elements.

Logit: Swiss labour market participation

Cross-section data originating from the health survey SOMIPOPS for Switzerland in 1981.

library("AER")
data("SwissLabor", package = "AER")
head(SwissLabor)
##   participation   income age education youngkids oldkids foreign
## 1            no 10.78750 3.0         8         1       1      no
## 2           yes 10.52425 4.5         8         0       1      no
## 3            no 10.96858 4.6         9         0       0      no
## 4            no 11.10500 3.1        11         2       0      no
## 5            no 11.10847 4.4        12         0       2      no
## 6           yes 11.02825 4.2        12         0       1      no

Logit: fitting the model

SwissLabor <- SwissLabor %>%
  mutate(participation = ifelse(participation == "yes", 1, 0))
glm_fit <- glm(
  participation ~ age + education + youngkids + oldkids + foreign,
  data = SwissLabor,
  family = "binomial"
)

Note how little changes from lm(): same formula interface, plus a family argument.

Logit: results

summary(glm_fit)
## 
## Call:
## glm(formula = participation ~ age + education + youngkids + oldkids + 
##     foreign, family = "binomial", data = SwissLabor)
## 
## Coefficients:
##              Estimate Std. Error z value Pr(>|z|)    
## (Intercept)  2.085961   0.540535   3.859 0.000114 ***
## age         -0.527066   0.089670  -5.878 4.16e-09 ***
## education   -0.001298   0.027502  -0.047 0.962371    
## youngkids   -1.326957   0.177893  -7.459 8.70e-14 ***
## oldkids     -0.072517   0.071878  -1.009 0.313024    
## foreignyes   1.353614   0.198598   6.816 9.37e-12 ***
## ---
## Signif. codes:  0 '***' 0.001 '**' 0.01 '*' 0.05 '.' 0.1 ' ' 1
## 
## (Dispersion parameter for binomial family taken to be 1)
## 
##     Null deviance: 1203.2  on 871  degrees of freedom
## Residual deviance: 1069.9  on 866  degrees of freedom
## AIC: 1081.9
## 
## Number of Fisher Scoring iterations: 4

We will revisit the regression models in much more detail in the later lectures.

R Markdown and Quarto


R Markdown

A document format that combines the power of R programming with the simplicity of Markdown syntax. Code, results, and narrative text coexist seamlessly.

R Markdown provides an authoring framework for data science. You can use a single R Markdown file to both

  • save and execute code
  • generate high quality reports that can be shared with an audience

Key features of R Markdown

  • Reproducible research: your analysis and results are automatically updated when you change your code or data.
  • Multiple output formats: HTML, PDF, Word documents, presentations and more, all from the same source.
  • Code integration: embed R code chunks that execute and display results inline with your text.
  • Version control friendly: the plain text format works well with Git and other version control systems.

Basic structure

An R Markdown document consists of three main components:

  1. YAML header: metadata and output options, enclosed by ---
  2. Markdown text: regular text formatted with Markdown syntax
  3. Code chunks: R code blocks enclosed by triple backticks with {r}

This deck, and the long-form note it mirrors, are themselves such documents.

Code chunks

Code chunks are the heart of R Markdown. They allow you to:

  • execute R code and display results;
  • control output with chunk options, e.g. echo=FALSE, eval=FALSE;
  • create plots, tables, and other visualizations;
  • cache results for faster compilation.

Getting started

Quarto

Quarto (.qmd) represents the next generation of R Markdown, building upon its foundation while introducing significant improvements.

  • Most R Markdown syntax remains compatible.
  • Enhanced features and better multi-language support, beyond just R.

For comprehensive documentation and tutorials, visit the Quarto website.